Stay in the IDE: Android Studio Rabbit 2 Goes Stable With 40+ Coding Agents Inside
At Android Dev Summit on October 28, Google shipped Android Studio Rabbit 2 to stable, with Bring Your Own Agent stable too: 40+ ACP-compatible coding agents can run inside the IDE with access to project structure, the emulator, and Logcat. This article covers what changed, how Change Review and Android CLI fit in, and a five-step way to try it.
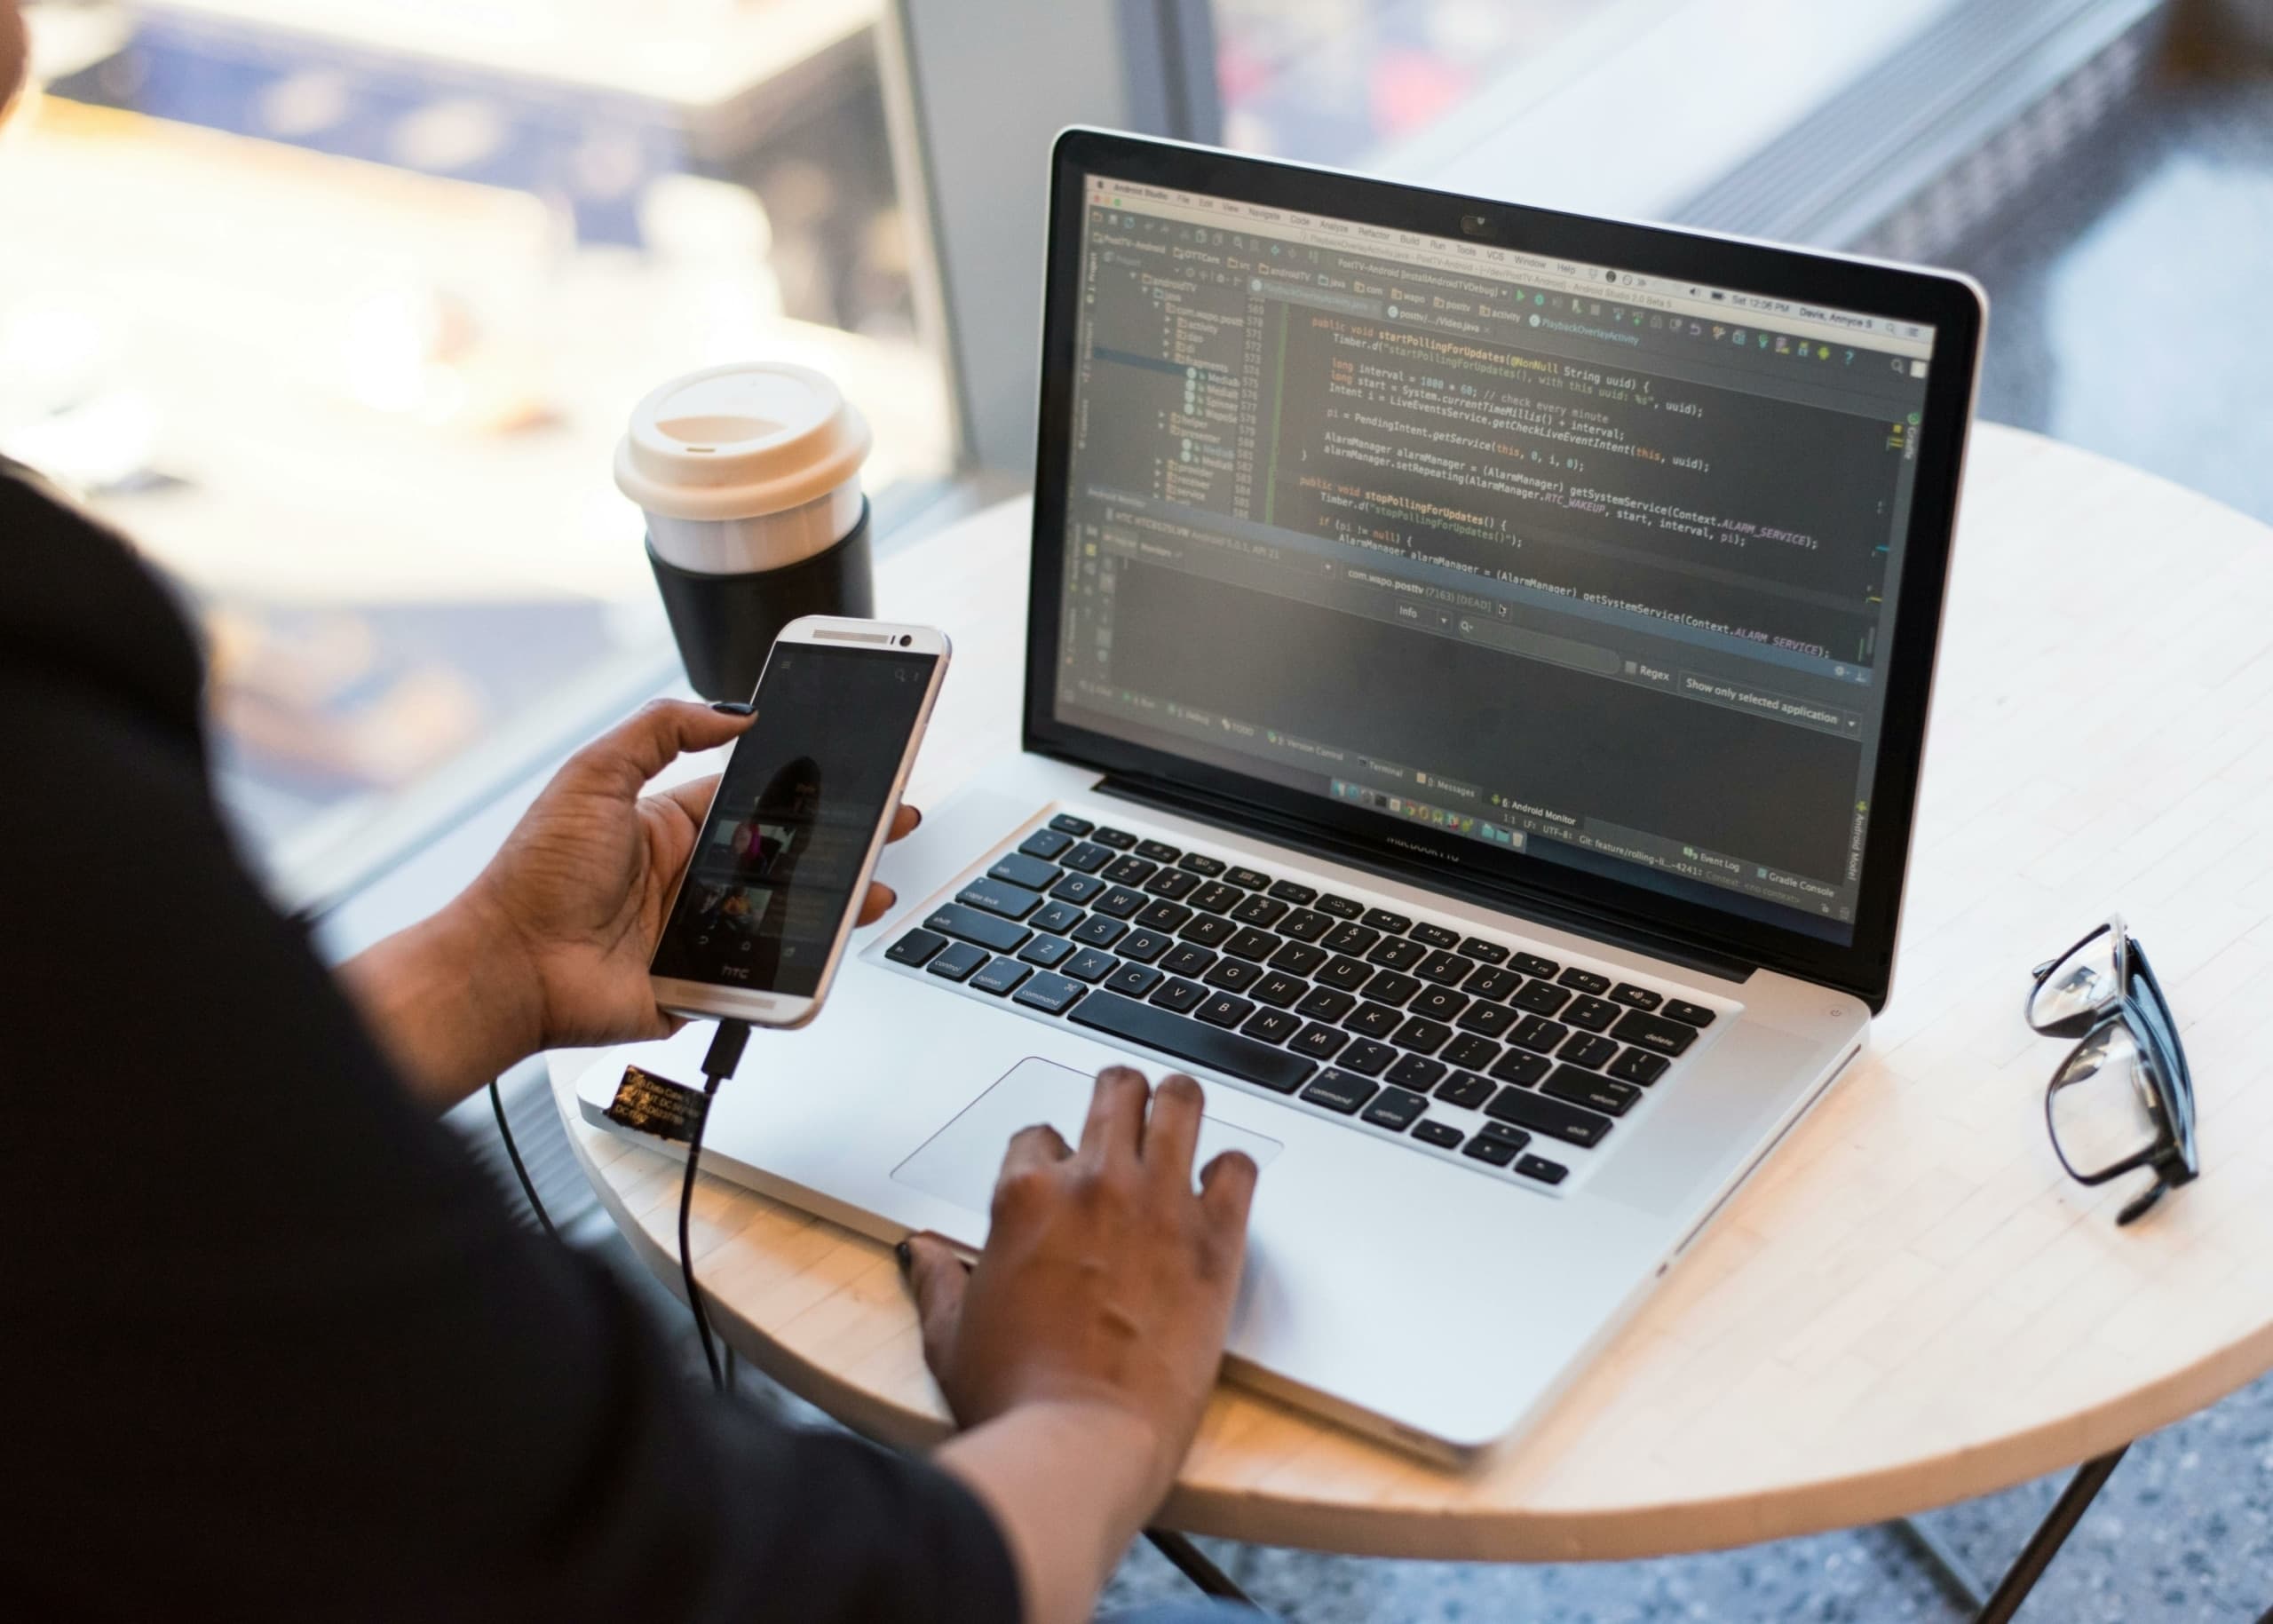

On October 28, at Android Dev Summit, Google moved something it had previewed earlier into the stable channel: Android Studio Rabbit 2 is out, and with it, Bring Your Own Agent (BYOA) is now stable. For Android developers, that ends a forced choice between "the agent I already pay for" and "the tools built into the IDE." Claude Agent, OpenAI's Codex, Google's own Antigravity, and more than 40 other agents that speak the open Agent Client Protocol (ACP) can now run directly inside Android Studio.
One clarification matters before anything else: BYOA itself is not new on October 28. It appeared in September 2026 as a Canary preview. This announcement is about it reaching stable. That distinction is the whole story for teams deciding whether to build a workflow on it. A preview is worth trying; a stable release is worth planning around.
What actually shipped
The core change is a change of attitude in the IDE. Android Studio's built-in AI assistant used to be Google's own, and outside agents had to sit in a terminal, looking at your project from one step away. BYOA brings outside agents inside: open Settings > Tools > AI > Agents to browse and install agents from the marketplace, install more than one, and switch between them as you work, without leaving the IDE.
What those agents get access to is the more important part. They inherit the IDE's own understanding of your project: its structure and build configuration, symbol resolution, Compose Preview rendering, the Emulator, and Logcat. In Google's framing, an agent with that view works less like a chatbot that reads your open file and more like a colleague sitting inside the IDE: change a screen, run it on the emulator, read the logs when it breaks, and go back and fix it. That loop is exactly where terminal-only agents lose the most time, because every verification step has to be relayed through you.
Several companion pieces shipped alongside. The first is Change Review, a new agentic code review experience. You can start a review from pending agent changes or from the Git changes window, and Android Studio generates a report of potential issues. You can also trigger it with the /review command in the agent tool window, ask for an AI-guided walkthrough of a longer change, and have your agent fix the issues it finds. Google is explicit about the motivation: when an agent makes a large change, it is hard for a human to understand what it actually did. Change Review is aimed at that gap.
The second is Android Bench 2.0, a leaderboard that evaluates models and agent harnesses on long-running, real-world Android tasks, the kind that take an engineer days: migrating a UI, or building an app from mocks. The grading rule is worth noting. Solutions are judged on whether they actually work, not merely whether they compile, and cost and time are measured too. For anyone choosing a model, that is a more honest yardstick than a benchmark score alone.
The third is the Android CLI track, which does not need the IDE open at all. New capabilities include streaming a real physical device from Google's device lab with android device remote, rendering Compose Previews without an emulator or an APK install through android preview, and official Android plugins for Claude Code and Codex that install with a single marketplace command. If you already drive your agents from the terminal, this track may reach you before the in-IDE version does.
The fourth is the performance track. LeakCanary is now integrated directly into Android CLI: heap dumps are analyzed on your own computer rather than on the device, and Google says the most capable models ran the leak-finding process almost twice as fast while using up to 25% fewer tokens. Treat that as Google's internal test result, not an independent measurement. Android Performance Analyzer now powers the CLI profiler too, paired with a new android-profiler skill, so an agent can capture traces, analyze them, propose fixes, verify the changes, and measure the impact. And android signals brings production crashes, ANRs, and memory issues from the field straight to the terminal and to your agent.
There is also a Migration Assistant for moving XML Views layouts to Compose, currently in Canary: right-click a layout and choose AI > Migrate to Compose, or run it across the project, and the agent scopes the work with you, drafts a plan, and converts layouts, view-binding code, and logic into idiomatic Compose, with a progress timeline you can resume from. Google also notes more than 30 official Android skills across more than 20 areas, including Play policy checks before submission and security reviews for intents and permissions. None of these is the headline on its own, but together they show the direction: from "write code" to the whole chain from a production signal to a verified fix.
Why this matters
For the past year, the AI coding race has mostly been argued over which model is stronger. Android Studio's move points at a different contest: which tool sits closest to the developer's real working environment. An agent that can only read and edit files does a different job from one that can run the emulator, read Logcat, and check production crashes. The first hands you code that looks right; the second has a chance to walk the loop of change, run, and verify on its own. Google is betting the second is worth more.
There is also a platform signal here. Google did not turn Android Studio into a storefront that only pushes its own Gemini assistant. It invited Claude and Codex in. A few years ago that would have been hard to picture: platform owners usually keep their own assistant in the most convenient spot and keep rivals at arm's length. Google has gone the other way, conceding that developers already pay for agents of their choice, and that owning the IDE matters more than owning any single assistant. For developers, the choice is back in their hands.
For solo developers and small teams, the practical payoff is about broken context. Time is already fragmented, and every window switch costs context: you used to copy an error into a terminal agent yourself. Now the agent can see the error itself. That step looks small, but it is one of the steps that decides whether vibe coding can actually deliver a working Android app rather than a convincing demo.
What to do with it
If you build Android apps with AI, or plan to, try it in this order. First, update to Rabbit 2 and install the agent you already use from Settings > Tools > AI > Agents, signing in with your own subscription. BYOA does not give you agents for free: the billing follows each agent's provider, while Android Studio's built-in agent remains available at no extra charge. Settle that account question before you talk about efficiency.
Second, do not hand it a large refactor on day one. Give it a small diagnostic task first: explain how one screen manages state, which files are involved, and propose a change before editing anything. Ten minutes of that tells you how accurately the agent understands your project, and how much latitude it deserves.
Third, let the agent do the verification, but keep acceptance for yourself. After it changes something, have it run the emulator and read Logcat, and run Change Review over its own diff. You check three things before merging: what behavior changed, why this approach was chosen, and how the result was verified. If you cannot answer those three, do not merge. That rule matters most for AI-generated changes, because the larger the diff, the easier it is to wave through something that merely looks right.
Fourth, if you live in the terminal, do not overlook the CLI track. android preview lets you check Compose screens without booting an emulator, which pays off when you are iterating on UI. android signals feeds live crashes to your agent, which beats pasting stack traces back and forth when you are fixing a production bug. Neither requires changing IDEs, so both are cheap to try.
Fifth, choose models with your own task, not with an advertisement. Android Bench 2.0's approach is worth copying: pick a real job from your own project, such as migrating a list screen from XML to Compose or fixing a memory leak, run each candidate agent on it, and measure three things: does it work, how many tokens did it cost, and how long did it take. Leaderboards are a reference; your own task is the standard.
Risks and open questions
Several things are not settled yet. First, the permission boundary. When an agent gains deep IDE abilities, including running the emulator and executing commands, someone has to decide which actions are routine and which require your approval. Google's Canary-era framing allows granular permissions that let agents act alone on routine work and pause on riskier actions, but the line for your project has to be drawn in practice, not assumed.
Second, Google's internal numbers — 77% faster UI tasks, up to 3x fewer tokens, nearly 2x faster leak finding — are vendor tests, not independently reproduced results. The mechanisms make sense, since skipping the emulator obviously saves time, but how much you save on your project has to be measured, not quoted to a boss or a client as a promise.
Third, the ecosystem is in a quantity-first phase. Forty-plus agents can be installed, but that does not mean all of them are equally good: ACP implementations differ in depth, in which IDE tools they can call, and in how they behave when something goes wrong. Pick one main agent, learn it well, and use a second as a control, rather than installing ten and cycling through them.
Fourth, the Canary pieces stay Canary pieces. The Migration Assistant and early build experiments such as Lightbuild are not production tools yet; try them on a throwaway branch, not on the project you ship. The stable BYOA release and the CLI plugins are the parts to adopt first.
The judgment, in one line: Android Studio is no longer competing mainly on whose model is cleverest, but on whose workbench is most complete. For vibe coding, that is good news, because the closer tools sit to a real development workflow, the closer a natural-language instruction gets to a shippable, repairable, publishable app. The condition has not changed, though: the verification step cannot be outsourced to the agent itself.
Comments (0)
Sources
Related articles
On October 28, GitHub announced Copilot code review Max in public preview, with multi-agent review across models, and Copilot approvals generally available, counting toward required approvals. This article explains where Max fits, the four rules to set before AI may approve, and a five-step rollout checklist for small teams.

On October 28, GitHub put Copilot Projects into public preview: work-centered, multi-agent coordination across repos and documents, with automations and desktop computer use. This article explains how it works, when small teams should use it, and the real bottleneck — review speed.
On October 28, 2026, GitHub announced at Universe that Copilot Fusion is generally available: users pick only an effort level while the system decides mid-task which model to use, whether to escalate, and whether to critique. This piece follows the official changelog through the three tiers and three execution patterns, and explains how to read the benchmark numbers and the post-discount price.