Stop Guessing How Happy Users Are: In-Product Surveys and NPS for Vibe Projects
Surveys and NPS turn 'feels fine' into a number you can compare and track. This guide covers NPS, CSAT, and CES selection, the exact NPS formula, seven rules for writing questions, timing and sampling, sample size and bias, reading open answers, and closing the loop so results become shipped fixes.
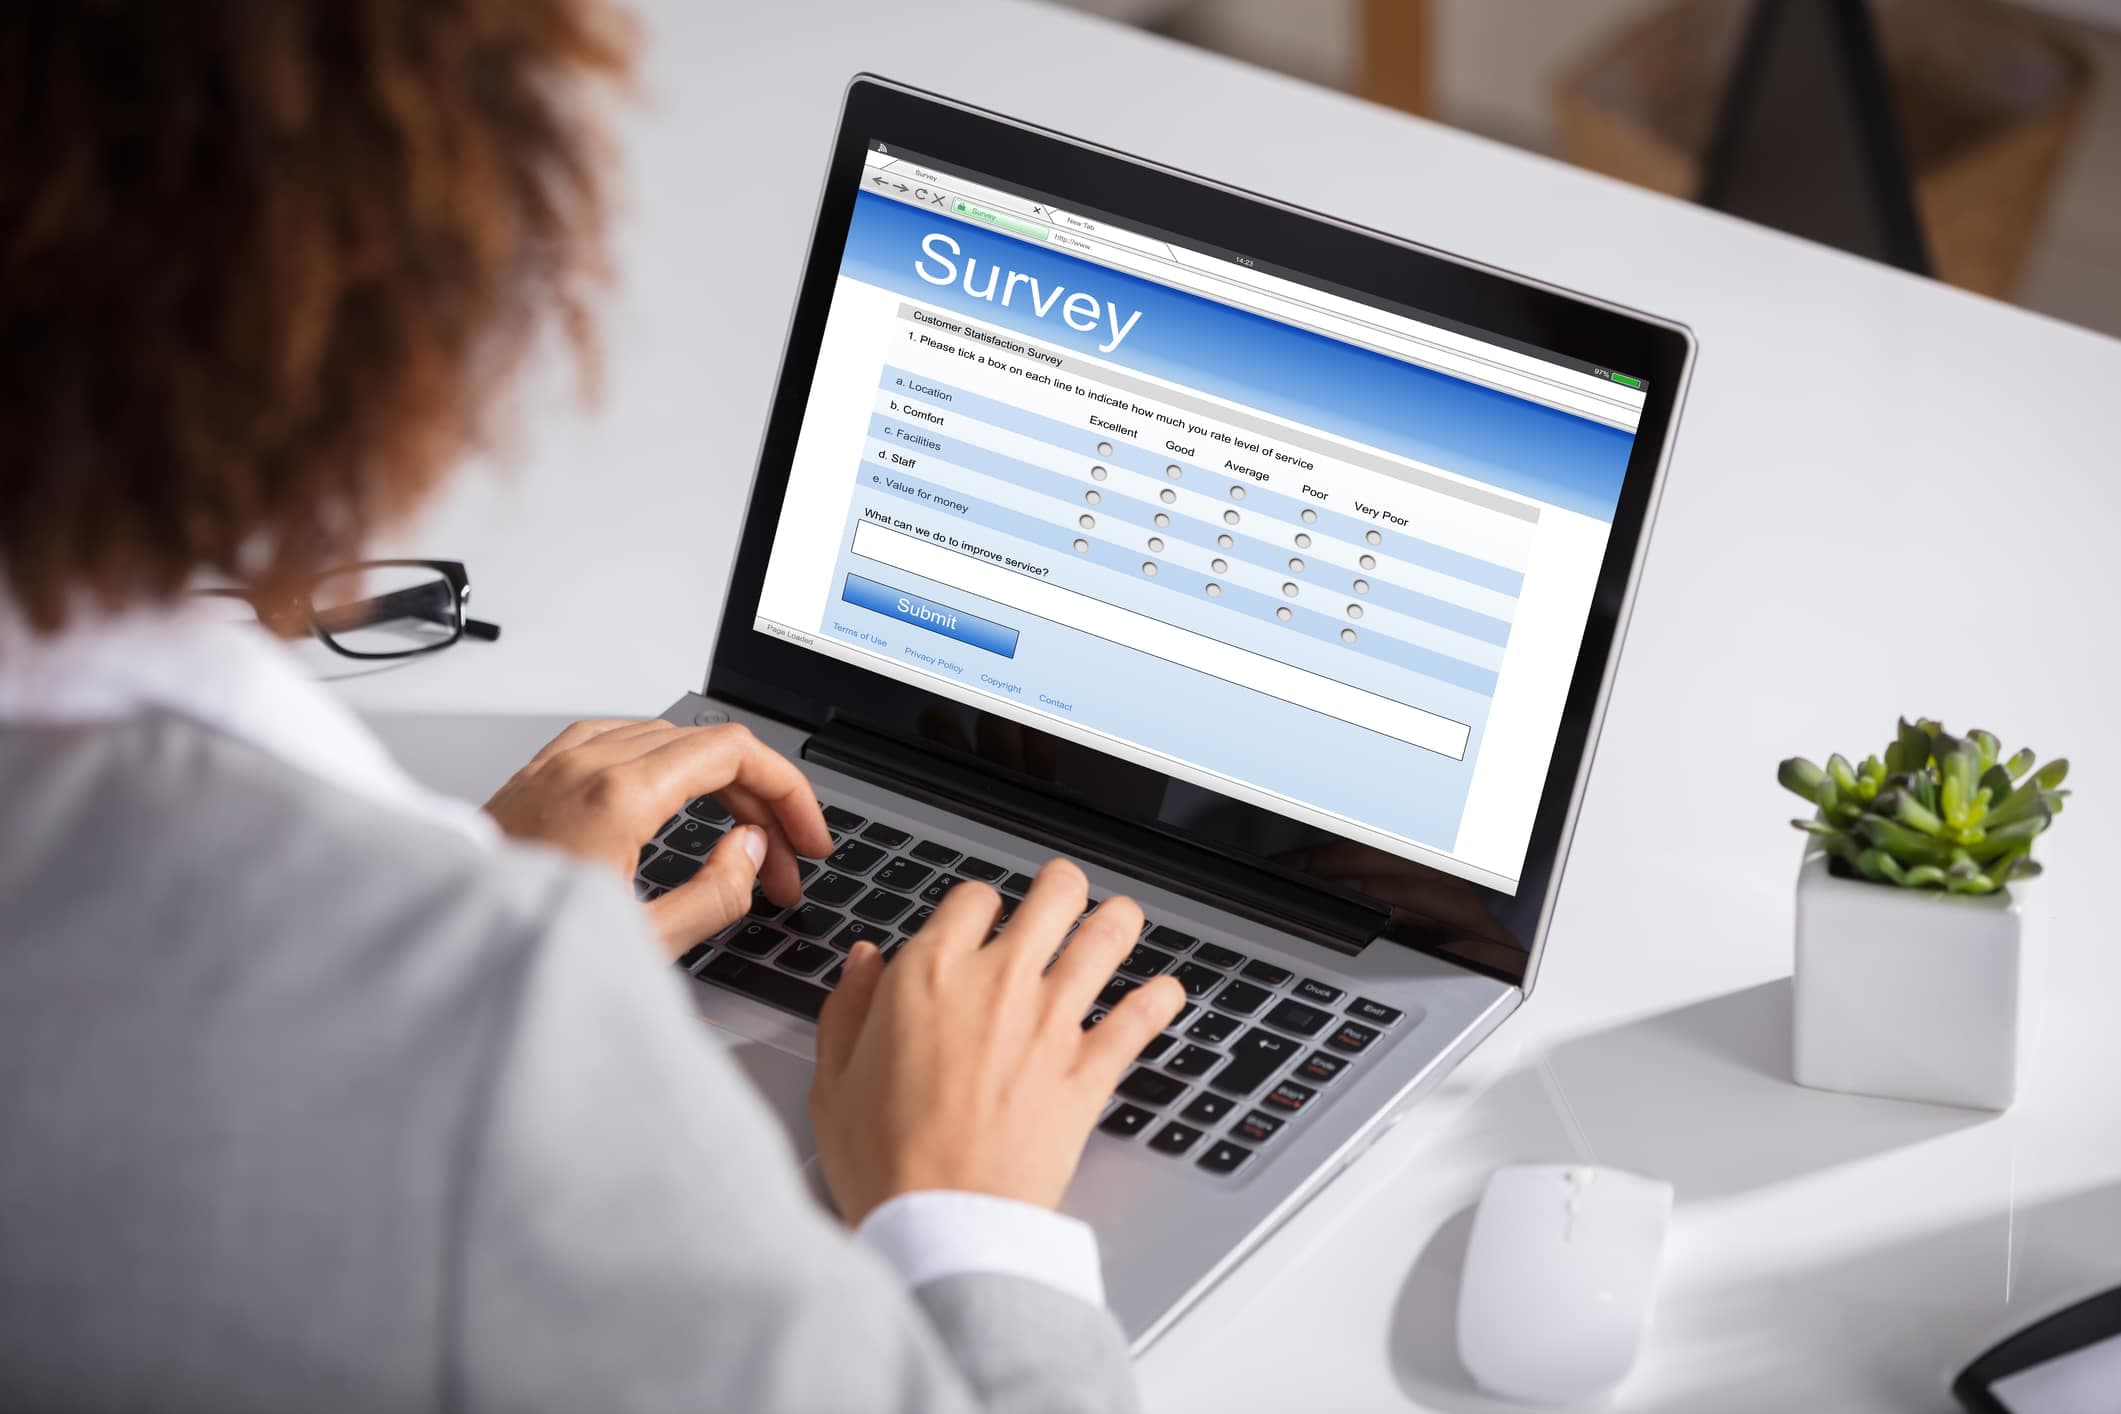
Here is a familiar feeling: your product has been live for six months, the dashboard numbers look fine, and yet you have no idea how users actually feel. Are they satisfied? What hurts them most? What should the next version fix first? You ask friends and they say "it is pretty good." You check the app store and find three reviews, one of which complains about your icon. Surveys and NPS exist to fix exactly this: a standardized measuring stick, applied regularly, that turns "feels fine" into a number you can compare and track.
First, the boundaries. The site already has a guide on user interviews and needs validation — one-on-one interviews, the Mom Test, the rule of five — which digs deep into open questions like "what do users actually want?" This guide covers the quantitative side: surveys, NPS, CSAT, CES, answering countable questions like "how many users are satisfied, and is satisfaction rising or falling?" Two more neighbors need distinguishing. The user-feedback loop guide covers what happens after feedback arrives — how to respond and close the loop. The feedback triage guide covers how to classify feedback when there is too much of it. This guide covers only the upstream step: how to design a survey, how to compute NPS, and how to read the results. Interviews dig deep, surveys measure wide, and the feedback loop handles the aftermath — three different jobs, not substitutes for one another.
All products, people, and figures in this guide are fictional examples: the fictional product is "Skylark Docs," an online collaborative document tool, and the fictional user is "Xiao Yu." All NPS scores, response counts, and rates are illustrative fictional numbers, not survey data from any real product.

1. Define the question before the questionnaire
Most surveys fail before a single question is written: the author does not know what they want to learn, so they send the survey first and figure it out later. The correct order is always: write down the questions you want to answer, then design the items, and only then decide who receives it and when.
There are three kinds of questions, each matched to one scale. The first is "would users recommend us?" — measured by NPS (Net Promoter Score). This is the most general health metric, best measured once a quarter to watch the trend. The second is "was this one experience satisfactory?" — measured by CSAT (customer satisfaction score). For example, right after a user finishes an export, ask "how would you rate this export experience?" It is triggered by events. The third is "how hard was this to do?" — measured by CES (customer effort score). After a user completes registration, ask "how easy was it to sign up?" It is the right tool for finding friction in a flow.
Never mix the three scales in one survey. One survey measures one thing: NPS, CSAT, or CES. Mix them and every number becomes unreliable, because you no longer know what the user was rating. Which one to pick depends on what worries you most this quarter: worried about retention, measure NPS; worried about a specific feature, measure CSAT; worried the flow is too convoluted, measure CES.
Another beginner mistake is treating the survey as a feature request box. "What features do you want us to add?" returns a wish list that cannot be prioritized. Feature needs belong in interviews; surveys measure satisfaction. Mix up the jobs and the survey gets longer, emptier, and less answered.
2. How NPS is actually calculated: one formula, three groups
The NPS question is exactly one sentence: "On a scale of 0 to 10, how likely are you to recommend our product to a friend or colleague?" Nothing more. No decoration, no explanation, no emoji. Change the wording and the score can no longer be compared with anyone else's — or with your own last quarter.
The calculation has three steps. First, sort respondents into three groups by score: 9 and 10 are Promoters, 7 and 8 are Passives, 0 to 6 are Detractors. Note that 7 and 8 do not mean "fairly satisfied" — in the NPS formula they count for nothing, neither adding nor subtracting. Second, subtract the Detractor percentage from the Promoter percentage. Third, multiply by 100. The result is the NPS, ranging from -100 to +100.
Fictional example: Skylark Docs collected 200 NPS responses this quarter — 90 people scored 9 or 10, 70 scored 7 or 8, and 40 scored 0 to 6. Promoters are 45%, Detractors are 20%, so NPS equals 45 − 20 = 25. The number has no absolute good or bad: above 0 means Promoters outnumber Detractors, above 50 is already excellent, and above 70 is world-class. For a solo team, whether the first reading is 10 or 30 hardly matters. What matters is which direction it moves next quarter.
Two common misreadings to avoid in advance. First, NPS is not satisfaction. A user can be very satisfied with your product and still refuse to recommend it — recommending puts their own reputation on the line. Conversely, a user can complain about your product daily and still recommend it, because there is no alternative. NPS measures willingness to recommend, not satisfaction; do not treat the two as synonyms. Second, do not compare your NPS directly with other products. Baselines differ wildly across industries and audiences — a tool product and a social product live on different scales. The only meaningful comparison is with your own history.

3. Seven rules for writing questions
Besides the standard NPS item, a survey usually needs two or three follow-up questions that explain what sits behind the score. Seven hard rules govern question design. Break any one of them and the data you collect will be distorted.
One: ask one thing at a time. "Are you satisfied with our export speed and interface design?" is a double question: the user may like the speed and hate the interface, and will pick an answer at random, leaving you unsure which half they answered. Split it into two questions, or ask only the more important half.
Two: no leading questions. "Don't you also think the new interface is much better?" already contains the answer. Users will agree to be polite, and what you get back is self-comfort, not data. Use neutral wording: "How would you rate the new interface?"
Three: options must be exhaustive and mutually exclusive. Ask "how did you hear about us?" with only "friend recommendation" and "search engine" as options, and users who came from social media are forced to pick a wrong answer. Always add "Other" plus a free-text field. Options must not overlap — "daily" and "often" side by side leave users guessing.
Four: keep the scale direction consistent. If 5 means "very satisfied" in one question and "very dissatisfied" in another, users will misanswer by the end of the survey. One rule for the whole survey: higher is better, stated in the question text, not just in the first item.
Five: at most one open question, and put it last. Open questions are the most valuable part of a survey — users describing a frustration in their own words beats any rating scale. They are also the most expensive in user time. Two or more open questions and the completion rate falls off a cliff. Keep exactly one: "Anything else you would like to tell us?" — placed last, optional.
Six: the whole survey must take under three minutes. The rule of thumb: completion is highest at five questions or fewer, and beyond ten questions each extra question costs 5% to 10% of completions. After writing the questions, fill it in yourself with a stopwatch. Over three minutes, cut questions. If a question cannot be cut, you are trying to ask too much — split it across two rounds.
Seven: never ask what you already know. Registration date, usage frequency, payment status — all of that lives in your backend. Asking again in a survey tells the user you do not know them at all. Surveys ask only for what the backend does not have: feelings, intentions, reasons.
4. Timing and sampling: do not block a busy user
Who receives the survey, and when, decides both the response rate and the data quality. Timing first: the best moment is right after the user completes a whole task. A Skylark Docs user has just finished a document and hit share — asking "how was this experience?" at that moment catches a fresh, specific feeling, and answer quality is highest. The worst moments are when the user just opened the product, or is rushing to finish something — block a busy person to ask if they are satisfied, and they will give you a low score out of spite.
The cooling-off period is a hard rule: the same user receives a survey at most once in 90 days. Do not send monthly; quarterly is the ceiling. Users who see surveys constantly learn one thing: the survey can be closed, and closing it costs nothing. The less often you ask, the more seriously users answer.
Sampling beats sending to everyone. With 50,000 monthly active users, a full send brings back thousands of responses you cannot process — and the respondents are all from the two extremes, the delighted and the furious, while the silent majority in the middle stays silent. Sample randomly instead: each round, randomly pick 5% to 10% of active users, and 200 to 400 responses is enough. Fictional example: Skylark Docs has 20,000 monthly actives; sampling 10% each quarter means 2,000 invitations, and at a 15% response rate that yields 300 replies — small enough error for NPS purposes.
Watch out for one sampling trap: surveying only active users. Churned users are the voices you most need to hear, but they no longer open the product, so in-app surveys never reach them. The fix: each quarter, sample a batch of churned users and email them a minimal survey — one NPS question plus one open question. With a subject line like "Two questions, 30 seconds," the response rate will be higher than you expect.
5. How many responses are enough: sample size and bias
"We got 30 responses and our NPS is 40" is a nearly meaningless sentence. With 30 responses the margin of error is wide enough to turn 40 into 10 or into 70. The practical floor for NPS is 100 valid responses; below that, swings mostly reflect luck, not product changes. Two hundred to 400 is the sweet spot — beyond that, extra precision buys very little.
More dangerous than sample size is bias. Survey responses carry three built-in biases, and every one of them inflates your score. First, survivorship bias: the people still using your product are, by definition, the more satisfied ones. The dissatisfied left long ago and you cannot reach them. NPS is optimistic by nature — discount it when you read it. Second, extremity bias: the very satisfied and the very angry are the most motivated to fill in surveys, while the 70% in the middle who think "it is fine" do not bother. Your score reflects the two ends, not the middle. Third, incentive bias: offer a reward ("fill in the survey and enter a draw for $100") and responses go up, but the people answering are there for the reward, and answer quality goes down.
Three defenses exist. First, never look only at the average — look at the distribution. An NPS of 25 can mean "45% Promoters, 20% Detractors" or "70% Promoters, 45% Detractors," and the problems behind those two distributions are completely different: too many Passives in the first case, too many Detractors in the second. Read the distribution before drawing conclusions. Second, slice the data. Cut NPS by segment — new versus old users, free versus paying, different acquisition channels — and the scores often differ by more than 20 points. Averages hide the truth; slices reveal it. Third, keep rewards restrained. If you must reward, use a prize draw, not a reward for everyone: a draw attracts a few people, while a guaranteed reward attracts everyone — including people who never used the product and only want the prize.
6. Reading open answers: finding three things in a hundred sentences
Open answers are the hardest part to process: a hundred responses are a hundred sentences in plain language, all talking past each other, looking like a mess. The method is coding: read 30 responses, extract 6 to 10 categories, then classify the remaining 70 one by one. Example categories: slow, missing feature, confusing interface, too expensive, slow support, unstable. Allow one sentence into two categories at most — beyond that, the categories lose their meaning.
After coding, compute two things per category: how often it appears, and the average NPS of the users who mentioned it. Categories that are frequent and low-NPS are what the next version should fix first. Fictional example: in Skylark Docs this quarter, "too few export formats" appeared 42 times, from users whose average NPS was just 5; "want a dark mode" appeared 35 times, from users averaging 40. The conclusion is clear: build export formats first, push dark mode back. Users say they want dark mode, but what actually makes them want to leave is export formats.
One more technique: read what the Detractors (0–6) wrote, specifically. Promoters' words are nice to hear, but they were satisfied already; Detractors' words are the action list. Three sentences from one Detractor are often worth more than praise from ten Promoters. Each quarter, print out the Detractors' open answers and read them together as a team. It beats any dashboard.
7. Closing the loop: a score that changes nothing was a wasted survey
The biggest waste in surveys is not that nobody answers — it is that answers arrive, nobody reads them, and nothing changes. Closing the loop has three steps, and skipping any one breaks it. Step one: reply to Detractors within 48 hours. A user scored you 3; within two days send an email: "We saw your score of 3 — could you tell us what went wrong?" Even if they never reply, the email itself signals that someone is listening. Many users move from Detractor to Passive on the strength of that one email.
Step two: publish what you learned in the changelog. Once a quarter, write "What we learned from the survey": NPS rose from 18 to 25 mainly because we fixed export formats; next quarter we will focus on slow sync. Publishing this does two things: people who answered feel their time was not wasted, and people who did not answer are more likely to answer next time.
Step three: turn survey findings into development tasks. The top three problems in each category go straight into the same backlog as every other feature request, with the same prioritization. Do not keep a separate "survey improvement list" — a separate list always ends up last. At the quarterly review, the first check is: of last quarter's top three survey problems, how many did we fix this quarter?
8. Tooling: start with off-the-shelf, do not build your own yet
Survey tools come in three tiers. Tier one is general SaaS: Typeform, Wenjuanxing, Google Forms. Sign up and go — right for a team running its first survey. The advantage is zero development and plenty of templates; the disadvantage is that data sits with someone else, styling is limited, and NPS must be computed from an export. Tier two is embedded NPS tools: Delighted, Wootric, Satismeter — services built for NPS that embed in your product and trigger on events. The advantage is that trigger logic, cooling-off periods, and sampling come ready-made; the disadvantage is a monthly fee that grows with your user base. Tier three is self-built: your own survey component, your own answer storage, your own NPS calculation. This fits teams that run surveys every quarter on a fixed cadence and care about data ownership.
The recommendation: for your first survey, use Google Forms or Wenjuanxing and run one quarter to test whether the survey itself is worth anything. If you decide to keep going in quarter two, consider an embedded tool. Self-build only when your trigger logic is genuinely unusual — for example, it must react to user behavior in real time — and off-the-shelf tools cannot integrate. Do not self-build on day one: the value of a survey lives in question design and in acting on results, not in the form component.
If you do self-build, keep at least three tables: survey sends (who, when, which channel), responses (who answered, each answer, time taken), and user survey status (when they last received a survey — used to enforce the 90-day cooling-off). Record time taken: ten questions answered in twenty seconds are almost certainly random clicks, and should be excluded from analysis.
9. Launch checklist and common pitfalls
Tick every item before sending: the questions you want to answer are written down, no more than three of them; one survey measures exactly one scale (NPS, CSAT, or CES — pick one); the NPS question uses the standard wording, unchanged by a single word; no more than 8 questions total, and your own timed run-through is under three minutes; exactly one open question, placed last; the trigger fires after a task is completed, not when the product opens; the same user receives a survey at most once in 90 days; the sampling rate is set (5% to 10%), and churned users have a separate email survey; someone owns the 48-hour Detractor reply process; time-taken is recorded so random clicks can be excluded.
Finally, the five most common pitfalls. One: opening with "how satisfied are you overall?" — with no concrete scenario to anchor on, users answer from vague impressions and the score is useless. Always give a scenario first, then ask for a feeling. Two: sending to everyone, letting the two extremes hijack the result while the silent majority stays silent — sampling is more accurate than a full send. Three: putting a guaranteed reward in the survey and collecting answers from people chasing the prize — keep rewards restrained; a draw beats a handout. Four: celebrating when NPS rises and blaming the sample when it falls — check sample size and distribution before blaming the product. Five, the easiest to overlook: survey results circulate only inside the team and users never hear back — next quarter's response rate will drop, because users learned that answering changes nothing. Spend half an hour each quarter writing "what we learned and what we changed" for your users. That half hour is the highest-return step in the whole survey process.
Surveys and NPS are not about obtaining a flattering score. They exist to build an honest feedback loop: measure regularly, read carefully, change publicly. The score itself can deceive — survivorship bias, extremity bias, incentive bias can each inflate it. But measured quarter after quarter, the trend does not lie: rising means you are doing the right things; falling means there are things users have stopped bothering to tell you twice.
Comments (0)
Related articles
Users are not one crowd — they are a crowd of people in completely different situations. This guide covers behaviour-first segmentation with the RFM starting point, four implementation approaches from static lists to model scoring, rule priorities and mutual exclusion, channels and frequency caps, control-group measurement, privacy floors, and a 13-item launch checklist.
A gift card is not a coupon with a different name: the giver pays first, the recipient spends later, and the money is a liability until it is spent. This guide covers the three forms, the five-step purchase flow, redemption code design against brute force, the balance ledger, fraud prevention, refunds and support, and a 14-item launch checklist.
Analytics tells you something is wrong somewhere; session replay shows you exactly what happened. This guide covers what replay records and what it must never record, sampling rates, privacy in four layers, how to read click, scroll, and movement heatmaps, a weekly replay review routine, and a 12-item launch checklist.