More Feedback, Less Chaos: A User Feedback Triage Funnel for Vibe Projects
More feedback should not mean more chaos. This guide gives small teams a triage funnel: one intake, four buckets (broken, missing, confusing, wanted), deduplication, four-dimension scoring, a thirty-minute weekly meeting, and reply loops — including how to decline without burning trust.
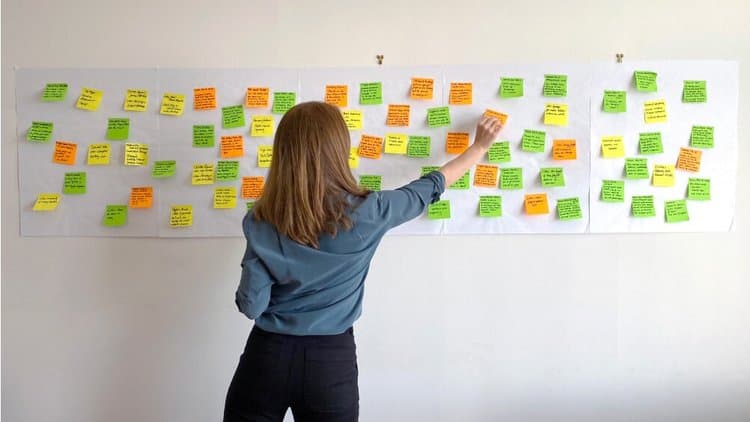

The happiest problem after a product launch is that feedback suddenly multiplies: it arrives by email, on social media, in the in-app feedback form, and in user groups. At first, every message is exciting. Within a few weeks, excitement turns into anxiety: which one do we handle first? Which one is a real problem and which is personal preference? Which one has already been raised by ten people, and which is the same bug described differently? Without a triage method, more feedback means more chaos, and the usual outcome is that the most urgent items get buried, the loudest get prioritized, and the needs of the majority go unaddressed. This guide offers a feedback triage funnel for small teams: intake, classification, deduplication, scoring, a weekly triage meeting, and reply loops — each step with practices you can use directly.
Step one: consolidate intake before you process anything
The first layer of the funnel is not classification but consolidation. Feedback scattered across five channels cannot be triaged: you answer one by email, three more of the same appear in a group chat, and ten more sit unread in a form. Consolidation means choosing one single feedback intake and putting it where users can most easily find it. For most vibe projects, that can be a public feedback board, a form, or a dedicated email address. The tool does not need to be fancy; what matters is that every channel ultimately flows into the same place. You can keep chatting with users on social media and in groups, but valid feedback that emerges in conversation should be transcribed by a team member into the unified intake, not left to expire in chat history.
Consolidation also needs a rule: every feedback item must carry a scenario. Feedback without a scenario cannot be handled. "Export is bad" tells the handler nothing: exporting what, how much, on what device, stuck at which step? Ask three required questions in the form: what you were trying to do, what actually happened, and what device and version you used. Those three questions cost users little but cut most of the back-and-forth follow-ups. If feedback comes from a chat, add those three items when transcribing; if they cannot be filled in, ask one follow-up question first rather than pushing the item straight into processing.
Consolidation has another benefit: it reveals the true scale of feedback. Many teams feel "there is too much feedback to handle" without ever counting it. How many items arrive per week? How many are bugs, feature requests, or usage questions? Count for one week and the numbers will tell the truth. It may turn out there are only twenty items a week — entirely manageable, just scattered so it looks like more. Or it may turn out there are over a hundred, and a triage mechanism is genuinely needed. Triage discussions without numbers are discussions based on feeling.
Step two: sort into four buckets before you rank anything
Once feedback is in, do not rush to rank it — classify it first. Use a four-bucket method, with each item going into exactly one bucket, classified by "what it is asking," not "how important it is." Bucket one, "Broken": something that should work does not — crashes, errors, data loss, or performance so bad it is unusable. Bucket two, "Missing": the user wants to accomplish something the product does not support — a capability gap. Bucket three, "Confusing": the capability exists, but the user could not find it, understand it, or used it wrongly — a usability and documentation problem. Bucket four, "Wanted": a new idea, direction, or scenario — a suggestion.
The value of the four buckets is that they separate handling paths too. "Broken" goes through a fix process until resolved. "Missing" goes through scheduling into roadmap discussion. "Confusing" goes through explanation and improvement — changing copy, guidance, or documentation. "Wanted" goes through evaluation — research first, then decide. Without classification, everything is mixed together, and teams waste meetings arguing the incomparable question of whether one bug matters more than one new feature. With buckets, discussion becomes ranking within a bucket, which is far more efficient.
Two classification mistakes are common. The first is mistaking "Confusing" for "Missing." A user says "there is no export feature" when they simply have not found the export button; treating that as a capability gap and scheduling development wastes a development cycle. The test: reproduce the user's path first. If the feature exists but the path is too deep, it is "Confusing" — fix guidance and copy before building anything. The second mistake is mistaking "Wanted" for "Missing." A user proposing a new idea does not mean the product lacks a capability; "Wanted" items need evaluation against product direction before scheduling. Misclassification sends all downstream handling in the wrong direction.
Step three: deduplicate — don't let one issue occupy five slots
After classification comes deduplication. When ten people describe the same issue in ten ways, and it occupies ten rows in the triage sheet, it looks like ten problems when it is actually one. Deduplication means creating one master record per issue, linking or attaching every feedback item that mentions it, and noting the mention count and representative scenarios. Mention count is itself an important signal: an issue raised by twenty people differs in priority from one raised by a single person — but without deduplication, that signal is drowned.
Watch out for cases that look different but are substantively the same. Three reports — "CSV export is garbled," "exported Chinese shows as question marks," "exported files look garbled in Excel" — are one encoding issue, not three. Judge sameness by reproduction path and root cause, not by the words users chose. Deduplication is best done by a fixed person — the product owner or a rotating team member — because its quality depends on familiarity with the product. Rotating too often splits one issue into several or merges several into one.
Deduplication has a side benefit: it surfaces the "silent minority." Some issues are mentioned rarely but coincide with churn or cancellations. Those deserve a separate flag even if their mention count is low. Add two fields to the master record: whether it is linked to churn or cancellation, and whether any paying user mentioned it. Those fields rescue "rare but fatal" issues from the long tail and prevent the blind spot of ranking purely by mention count.
Step four: score on four dimensions, not by volume of voice
Only after classification and deduplication comes ranking. The worst way to rank is by "who shouts loudest." The loudest users are not necessarily core users, and the most requested items are not necessarily the most valuable. Use a four-dimension score, 1 to 3 points each, 4 to 12 in total, as a ranking reference. Dimension one, reach: how many users encounter this, based on mention count relative to the user base. Dimension two, severity: completely unusable, partially limited, or merely inconvenient. Dimension three, direction fit: how well the issue matches the product's current direction — high-demand items that diverge from direction still need caution. Dimension four, implementation cost: changing one line of copy versus refactoring a module — lower cost scores higher.
Four-dimension scoring is not exact science. Its purpose is to force the team to consider four angles at once instead of relying on gut feeling. Score as a team rather than individually: one person's scores carry personal bias, while three people's averaged scores carry less. Scores also should not automatically equal schedule: if the highest-scored item requires refactoring a core module while the next release can only accommodate small changes, doing several lower-scored but low-cost items first is equally reasonable. Scores inform decisions; they are not decisions.
One special note: paying users' feedback should be flagged separately but should not automatically receive the highest score. Paying users deserve attention, but if one paying user's request runs entirely against product direction, satisfying them may harm the path of more free users converting to paid. The right approach: flag paying-user mentions, weigh the "reach" and "direction fit" dimensions more heavily in scoring, and do not give paying feedback an automatic fast lane. In the long run, a product that stays true to its direction retains more paying users.
Step five: a weekly triage meeting with a fixed agenda
The funnel needs an engine, and that engine is a weekly triage meeting of no more than thirty minutes. The fixed agenda: the first ten minutes cover new feedback — only this week's newly classified and deduplicated master records, one sentence each on the issue and its score. The middle ten minutes decide — assign each master record a clear destination: fix, schedule, change copy, research, or close. The last ten minutes handle backlog — look at master records without a destination for over two weeks and decide whether to advance or close them. Items without a destination must not be left for next week, because "next week" is the most common source of backlog.
Decisions must be recorded on the spot in a fixed format: issue, bucket, score, destination, owner, and next review time. Records turn feedback handling from memory-based to record-based: two weeks later, when a user asks about an item, you can immediately find its destination and owner instead of searching chat history. The recording tool follows the same "easy to maintain" principle: a table, a board, or the feedback board's own fields all work, as long as the whole team can see and edit them.
The triage meeting has another easily overlooked function: it is a fixed occasion for the team to align on product direction. Reviewing weekly what users actually struggle with makes the team's understanding of "who our users are and what troubles them" increasingly concrete — more directly than any market research report. Many small teams say "we have no time for meetings," but the time cost of not having a triage meeting is higher: everyone handles feedback from personal impressions, directions diverge, and the product ends up patched in all directions.
Step six: close the loop — tell users where their feedback went
The final layer of the funnel is replying. Handling feedback without telling the user is the same as not handling it — users do not know their voice was heard and will not speak up again. Replies fall into three cases. Case one, fixed: tell the user what was fixed, in which version, and thank them for the scenario — the more specific the scenario, the better, because users feel "my feedback was actually used." Case two, scheduled: tell the user which column it entered (linking to the relevant public roadmap item if applicable) and the rough expectation, but do not promise a specific date. Case three, declined: the hardest to write and the most important, covered separately below.
Reply timing matters too. Do not wait until everything is done to reply once; reply at each key node: "Received, classifying" on arrival; "Confirmed as issue X, now scheduling/fixing" after classification and scoring; and a final result message when done. Node-by-node replies cost little — many feedback tools support automatic notifications — but they let users know throughout the wait that "my feedback has not fallen into a black hole." The most painful part of waiting is not waiting itself but not knowing whether anyone is handling it.
For duplicate feedback merged into a master record, reply to everyone: send the result notification to every user who mentioned the issue, not just the first reporter. Batch replies multiply the trust return on a single fix tenfold: ten people who raised the same issue receive the "fixed" message at the same time, and all ten conclude "this team is reliable." Conversely, replying only to the first reporter leaves the other nine thinking the issue is unhandled — and they may raise it again, creating new triage load.
How to decline feedback without burning trust
Declining feedback is a craft. A bad decline reads: "We won't do this." Users hear dismissal and closure. A good decline has three elements: thanks, reason, and alternative. Thanks should be specific: "Thank you for describing in detail the scenario of exporting thousands of rows — a scenario we had not previously considered." The reason should be honest: "We are not doing this now because our direction is to serve small teams' daily feedback management first; bulk data export is outside that direction, and building it would dilute our focus." The alternative should be concrete: "For now, you can filter and export in batches — here are the steps. If our direction changes, we will re-evaluate this item."
Two traps to avoid when declining. The first is "pretending to consider": saying "we will seriously consider it" when the decision is already no. Users who wait three months and see no movement lose more trust than from a direct decline. If the decision is no, say no clearly and write down the reason. The second trap is "hiding behind technical jargon": users do not need to know your schema constraints; they need to know why "no" is reasonable for them. Translate the reason into user language — direction, priority, resources — not "our table structure doesn't support it."
There is a special case: the request is reasonable, but the team genuinely cannot do it now. Put it on a "revisit later" list and tell the user explicitly: "We agree with this item, but it cannot fit into the next two releases; we will re-evaluate it at the quarterly review." "Revisit later" is not an excuse for delay — it must have a review time, and at that time, whatever the outcome, the user must get an update. A "revisit later" without a review time is a disguised decline, and a less honest one.
How this guide relates to our other guides
This guide has a distinct role from other guides on this site. Feedback triage covers "how feedback is handled after it arrives"; the site's earlier feedback-loop guide (published 2026-10-09) covers the end-to-end loop from intake forms to monthly review — this guide is the triage step inside that loop (intake, sorting, dedup, scoring, weekly meeting), while that guide is the full chain. The acceptance checklist guide covers "how to judge whether a task counts as done"; this guide covers "how to judge whether a feedback item is worth doing" — one sets completion standards for tasks, one sets selection standards for feedback. The release-notes guide covers "how shipped content is written for users"; this guide's reply loop covers "how the outcome of a single feedback item is told to the person who raised it" — one is a broadcast announcement, one is an individual reply. The developer-docs guide covers "how to explain product capabilities"; this guide's "Confusing" bucket covers "how to improve guidance and documentation when users cannot find a feature" — one is the documentation itself, one is the mechanism for discovering documentation gaps. Read each as needed.
Closing: triage is not about handling more feedback, but about making fewer mistakes
Looking back at the funnel — intake, classification, deduplication, scoring, meetings, replies — its purpose is not to let you handle more feedback. Feedback can never be fully handled. Its purpose is to help you make fewer mistakes: fewer cases of treating "Confusing" as "Missing" and building unnecessarily, fewer cases of treating ten reports of one issue as ten issues, fewer rankings by volume of voice instead of value, fewer voices falling into black holes. For a small team, the greatest return on feedback triage is actually attention: thirty minutes of triage meeting a week buys the whole team a shared understanding of "what users are really struggling with." And shared understanding is the scarcest and most valuable thing a small team has. Start next week with the two simplest steps: set one unified intake, and count one week of feedback. Once numbers and intake are in place, the rest of the funnel will follow.
Comments (0)
Related articles
Loading, empty, and error states are not edge cases: they are what users meet on slow networks, new accounts, and bad days. This guide covers skeleton and progress rules, four distinct kinds of empty, error copy that protects user input, race conditions in state transitions, and an acceptance checklist.
A desktop-first web project is not mobile-usable just because it displays on a phone. This guide works through core-flow priorities, thumb zones, layout degradation for tables and charts, input and keyboard pitfalls, navigation and performance budgets, and a real-device acceptance checklist.
Google Cloud's October 21 announcement puts GPT-6 Astra, Sol, and Luna into Model Garden in private preview. The models are not new — the buying route is: Marketplace billing, commitment drawdown, and a single invoice. This article separates what is live from what is coming soon, and lists five common misreadings.