Alibaba Open-Sources OpenCodeReview: Two Years of Internal Battle-Testing, 40K Stars for 'Deterministic Pipelines + LLM Agents'
On September 21, Alibaba open-sourced OpenCodeReview, its AI code-review CLI: Apache-2.0, deterministic pipelines for the must-not-fail steps, LLMs only for dynamic analysis. Two years with tens of thousands of internal developers; 40K stars on arrival.
On September 21, TechGig reported that Alibaba had open-sourced OpenCodeReview, an AI-powered code review CLI under the Apache-2.0 license, written in Go. It shot up the GitHub trending charts: by September 24 the repo had roughly 40,000 stars and nearly 2,900 forks, with v1.12.9 shipping on September 22. In 2026, a year when everyone in AI coding is building agents, Alibaba's open-source strike targets a long-neglected but universally painful link in the chain: code review.
First, what it is. OpenCodeReview's positioning is admirably restrained: it doesn't generate code, it only reviews it. Hand it a git diff and it returns line-level comments flagging null-pointer exceptions, thread-safety issues, XSS, and SQL injection. The installation tells you it's a tool, not a companion: npm install -g @alibaba-group/open-code-review, then a single ocr review command runs it; it can emit JSON into CI pipelines and works with OpenAI- and Anthropic-compatible model endpoints. In other words, it doesn't want to be your pair-programming buddy — it wants to be your pipeline's gatekeeper.
What sets it apart is the architecture, summarized in one line: "deterministic pipelines + LLM agents." Deterministic engineering handles file selection, bundling, and rule matching — the steps that must never fail; the LLM agent handles only dynamic code analysis and context retrieval — what models are actually good at. The README states the motivation bluntly: this design exists to fix agents' classic review failures — large diffs skipping files, comment line numbers drifting, the same prompt stable on Monday and noisy on Tuesday. Per the official README, the tool's predecessor served as Alibaba's official internal AI code-review assistant for about two years, used by tens of thousands of developers and credited with finding millions of defects — the source of that "battle-tested" claim.
"Don't hand the whole review process to natural language"
OpenCodeReview's architectural manifesto is worth copying by everyone building AI applications: don't hand the whole process to natural language. Over the past two years, countless teams tried "general-purpose coding agent plus a few skills" for code review and hit the same wall: big PRs skip files, line numbers drift, prompts behave on Monday and misbehave on Tuesday. Alibaba's answer splits the process in two: deterministic engineering locks down the steps that must not fail; the model does what genuinely needs dynamic reasoning.
Behind that division is an honest assessment of model capabilities. LLMs excel at "read this code, understand what it does, imagine where it might break" — divergent, semantic work. They're bad at "walk 200 files precisely, guarantee none is missed, get every line number right" — mechanical, deterministic work. Making models do what they're bad at, then prompt-engineering them into stability, is the most common anti-pattern in AI applications of the last two years. OpenCodeReview's value isn't that it uses a stronger model (it lets you swap in any OpenAI/Anthropic-compatible one) — it's that it thought clearly about where the model should appear at all.
Concretely, the "deterministic pipeline" does roughly three things: file selection — deciding from the diff and dependency graph which files need review instead of dumping the whole repo into the model (the tokens saved here are themselves money); bundling — organizing related files into context blocks the model can actually comprehend in one pass, avoiding quote-out-of-context false positives; rule matching — running deterministic rules first to flag "obvious on sight" problems (hardcoded secrets, blatant SQL concatenation) without spending inference budget. After these three steps, the LLM agent receives an already pre-processed, structured, prioritized review task and only needs to do what it's best at: understanding business logic and catching subtle cross-file issues. This "converge first, then diverge" design is exactly how excellent human reviewers work — scan for obvious bugs first, then read closely for logic bugs.
The v1.12.3 release on September 16 is a telling footnote: it hardened security specifically — secret paths and per-environment .env files are no longer sent to the model by default, and a path-traversal bug in the code-search tool was fixed. A "code review tool" making "don't send secrets to the model" the default, in an era of agents everywhere, is a rare kind of self-awareness. It suggests those two years of internal磨炼 taught the security red lines through real incidents, not press releases.
A copy-paste playbook for bringing AI code review in-house
For readers wanting to move AI code review into their own teams, OpenCodeReview is directly copyable homework:
- Rules first, intelligence second. The built-in NPE, thread-safety, XSS, and SQL-injection checks are deterministic rules that don't depend on model "inspiration." An enterprise rollout's first step should be encoding its own coding standards as rules — not hoping the model "automatically finds everything."
- Output must be machine-readable. A design like ocr review --format json means review results can feed CI gates, quality dashboards, and metrics. A review tool that can only "print a few comments" won't survive three months in an enterprise pipeline.
- Model swappability is the floor. OpenAI/Anthropic-compatible interfaces mean enterprises can use private models, cheap models for first-pass screening, and strong models for re-review. Tying review capability to one vendor's model hands your quality lifeline to someone else.
- Secret red lines on by default. What v1.12.3 did should become standard for every AI coding tool: never send secrets and env vars to models by default, instead of making users configure allowlists themselves.
The subtext of this checklist: competition in AI code review will soon shift from "whose model is smarter" to "whose engineering is more solid." When every tool can plug into the strongest model, victory goes to whoever has the most complete rule library, the smoothest CI integration, the lowest false-positive rate, the most complete audit trail. That's all unglamorous grind — exactly what a player "ground down by tens of thousands of developers over two years" does best.
On the practical side, here's how an indie developer can start today. Step one: run ocr review locally over AI-generated code, focusing on secrets and injection issues — the cheapest safety net there is. Step two: pipe the JSON output into your GitHub Action so every PR triggers review automatically, making "AI review" as mandatory a gate as unit tests. Step three: gradually encode your team's own coding conventions as custom rules so the tool learns your codebase over time. Three steps, and a one-person side project gets near-big-tech quality gates for the price of a weekend's configuration.
The open-source gambit: Alibaba's position on the AI coding toolchain
Don't read OpenCodeReview as merely "a handy tool" — it's Alibaba staking a claim on the AI coding toolchain. The pieces are coming together: Qwen Code (Alibaba's official terminal coding agent, itself near 30,000 GitHub stars) handles "writing," OpenCodeReview handles "checking," and only "testing" is still missing — the direction is unmistakable: Alibaba doesn't want one hit tool, it wants the open standard for the whole "write–review–test" chain.
The playbook differs completely from the U.S. giants. Anthropic's strategy is a "model + official tools" closed loop: Claude Code and Claude Code Review orbit its own models, the moat is model capability. Google plays "model + ecosystem," with Gemini CLI open-sourced but centered on pulling developers into Google Cloud. Microsoft is "IDE-bound," with Copilot living inside VS Code. Alibaba's strategy is "open-sourced toolchain, open models": the tools aren't tied to its own models (they speak OpenAI/Anthropic-compatible APIs); the bet is on engineering practices validated by tens of thousands of developers. It's the classic "trade engineering for ecosystem" — model capability can be caught up with, but a rule library fed by millions of defects and stability ground out over two years of production is a time moat you can't copy.
For China's developer community there's another layer of meaning: this is the first time a Chinese tech giant has fully open-sourced something this central from its internal AI R&D infrastructure. Big-tech open source used to mean edge tools or marketing projects; code review is the heart of the R&D system. Open-sourcing OpenCodeReview publishes Alibaba's internal referee standard for "can this AI-written code merge." As more teams review to the same standard, the entire Chinese-speaking dev community's quality baseline quietly rises — that's open source's real compounding.
My take: code review is becoming the agent era's "guardrail business"
Zoom out and OpenCodeReview's open-sourcing is a signal: code review is graduating from "a step in the dev process" to the agent era's standalone "guardrail business." The logic is simple: when AI generates ten times the code humans write, review goes from "spot check" to "mandatory passage"; when agents can open PRs automatically, human review bandwidth becomes the bottleneck of the whole R&D system. Whoever controls the review gateway collects the quality tax on AI-written code.
The track is already crowded: Anthropic pushes multi-agent parallel review with Claude Code Review, GitHub Copilot bakes review into the PR flow, startups by the dozen sell "AI reviewers." Alibaba's differentiation is "open source + deterministic architecture": it doesn't compete on models, it open-sources the interface standard for what enterprise-grade review should look like — JSON output, rule libraries, CI integration. When enough teams build pipelines to that standard, Alibaba defines the rules of the game. Same playbook as Kubernetes back in the day: don't sell the product, sell the standard.
For the vibe coding community, the practical meaning is concrete. Indie developers and small teams could never afford "big-tech-grade" review: no dedicated reviewers on staff, and manual review can't keep up with AI-generated code velocity. Tools like OpenCodeReview mean a one-person team can have three quality gates: gate one, deterministic rules sweep (null pointers, injections, leaked secrets); gate two, an LLM agent's semantic review; gate three, humans only look at what the agent flagged. The cost is one npm command; the payoff is fewer 3 a.m. pager alerts.
A dose of calm to close. Nobody knows how many of those 40,000 stars are "bookmarked and never run"; the "millions of defects" is a company claim, unverified independently; a Go CLI isn't zero-friction for frontend teams either. But the direction is right: when everyone is making AI write more code, the people building tools for "fewer bugs" stand in the scarcer spot. Writing agents will keep getting cheaper; the ability to prove code correct will keep getting more expensive. OpenCodeReview is betting on exactly that future.
One more question worth everyone's thought: when the review tool itself uses AI — when "AI writes code, AI reviews code" becomes standard — where do human reviewers stand? OpenCodeReview's answer is hidden in its design: humans no longer read every line, but they define the rules (what counts as a problem), adjudicate disputes (the agent flagged it — do I agree?), and trade off false positives against misses. Humans move from "inspectors" to "legislators": you no longer find every bug, you define what a bug is. The same logic as the Devin-era "engineers become architects." Tools evolve; human positions move up — to the places where only humans can judge.
So stop treating code review as "the tail of the dev process." In the agent era it's the throat of the whole R&D system — code flows into production through it, quality is guaranteed by it, standards begin with it. Alibaba open-sourcing OpenCodeReview is publishing the blueprints for that throat. Whether you build from the blueprints or use the ready-made tool is each team's own choice; but "AI-generated code must pass automated review" should, starting this autumn, become the default in every vibe coder's workflow.
Sources
Related articles
On October 7, OutSystems announced Agent Experience is generally available: its low-code platform is now open to any AI coding agent — Claude Code, Cursor, Codex, Kiro — with agents working at the design level, the platform generating code deterministically, and governance built in. This is the "vibe coding goes enterprise" playbook: taming shadow AI with a compliant path. But the 74% rework figure is vendor-survey data — discount it. The real bill is the hidden cost of platform lock-in.
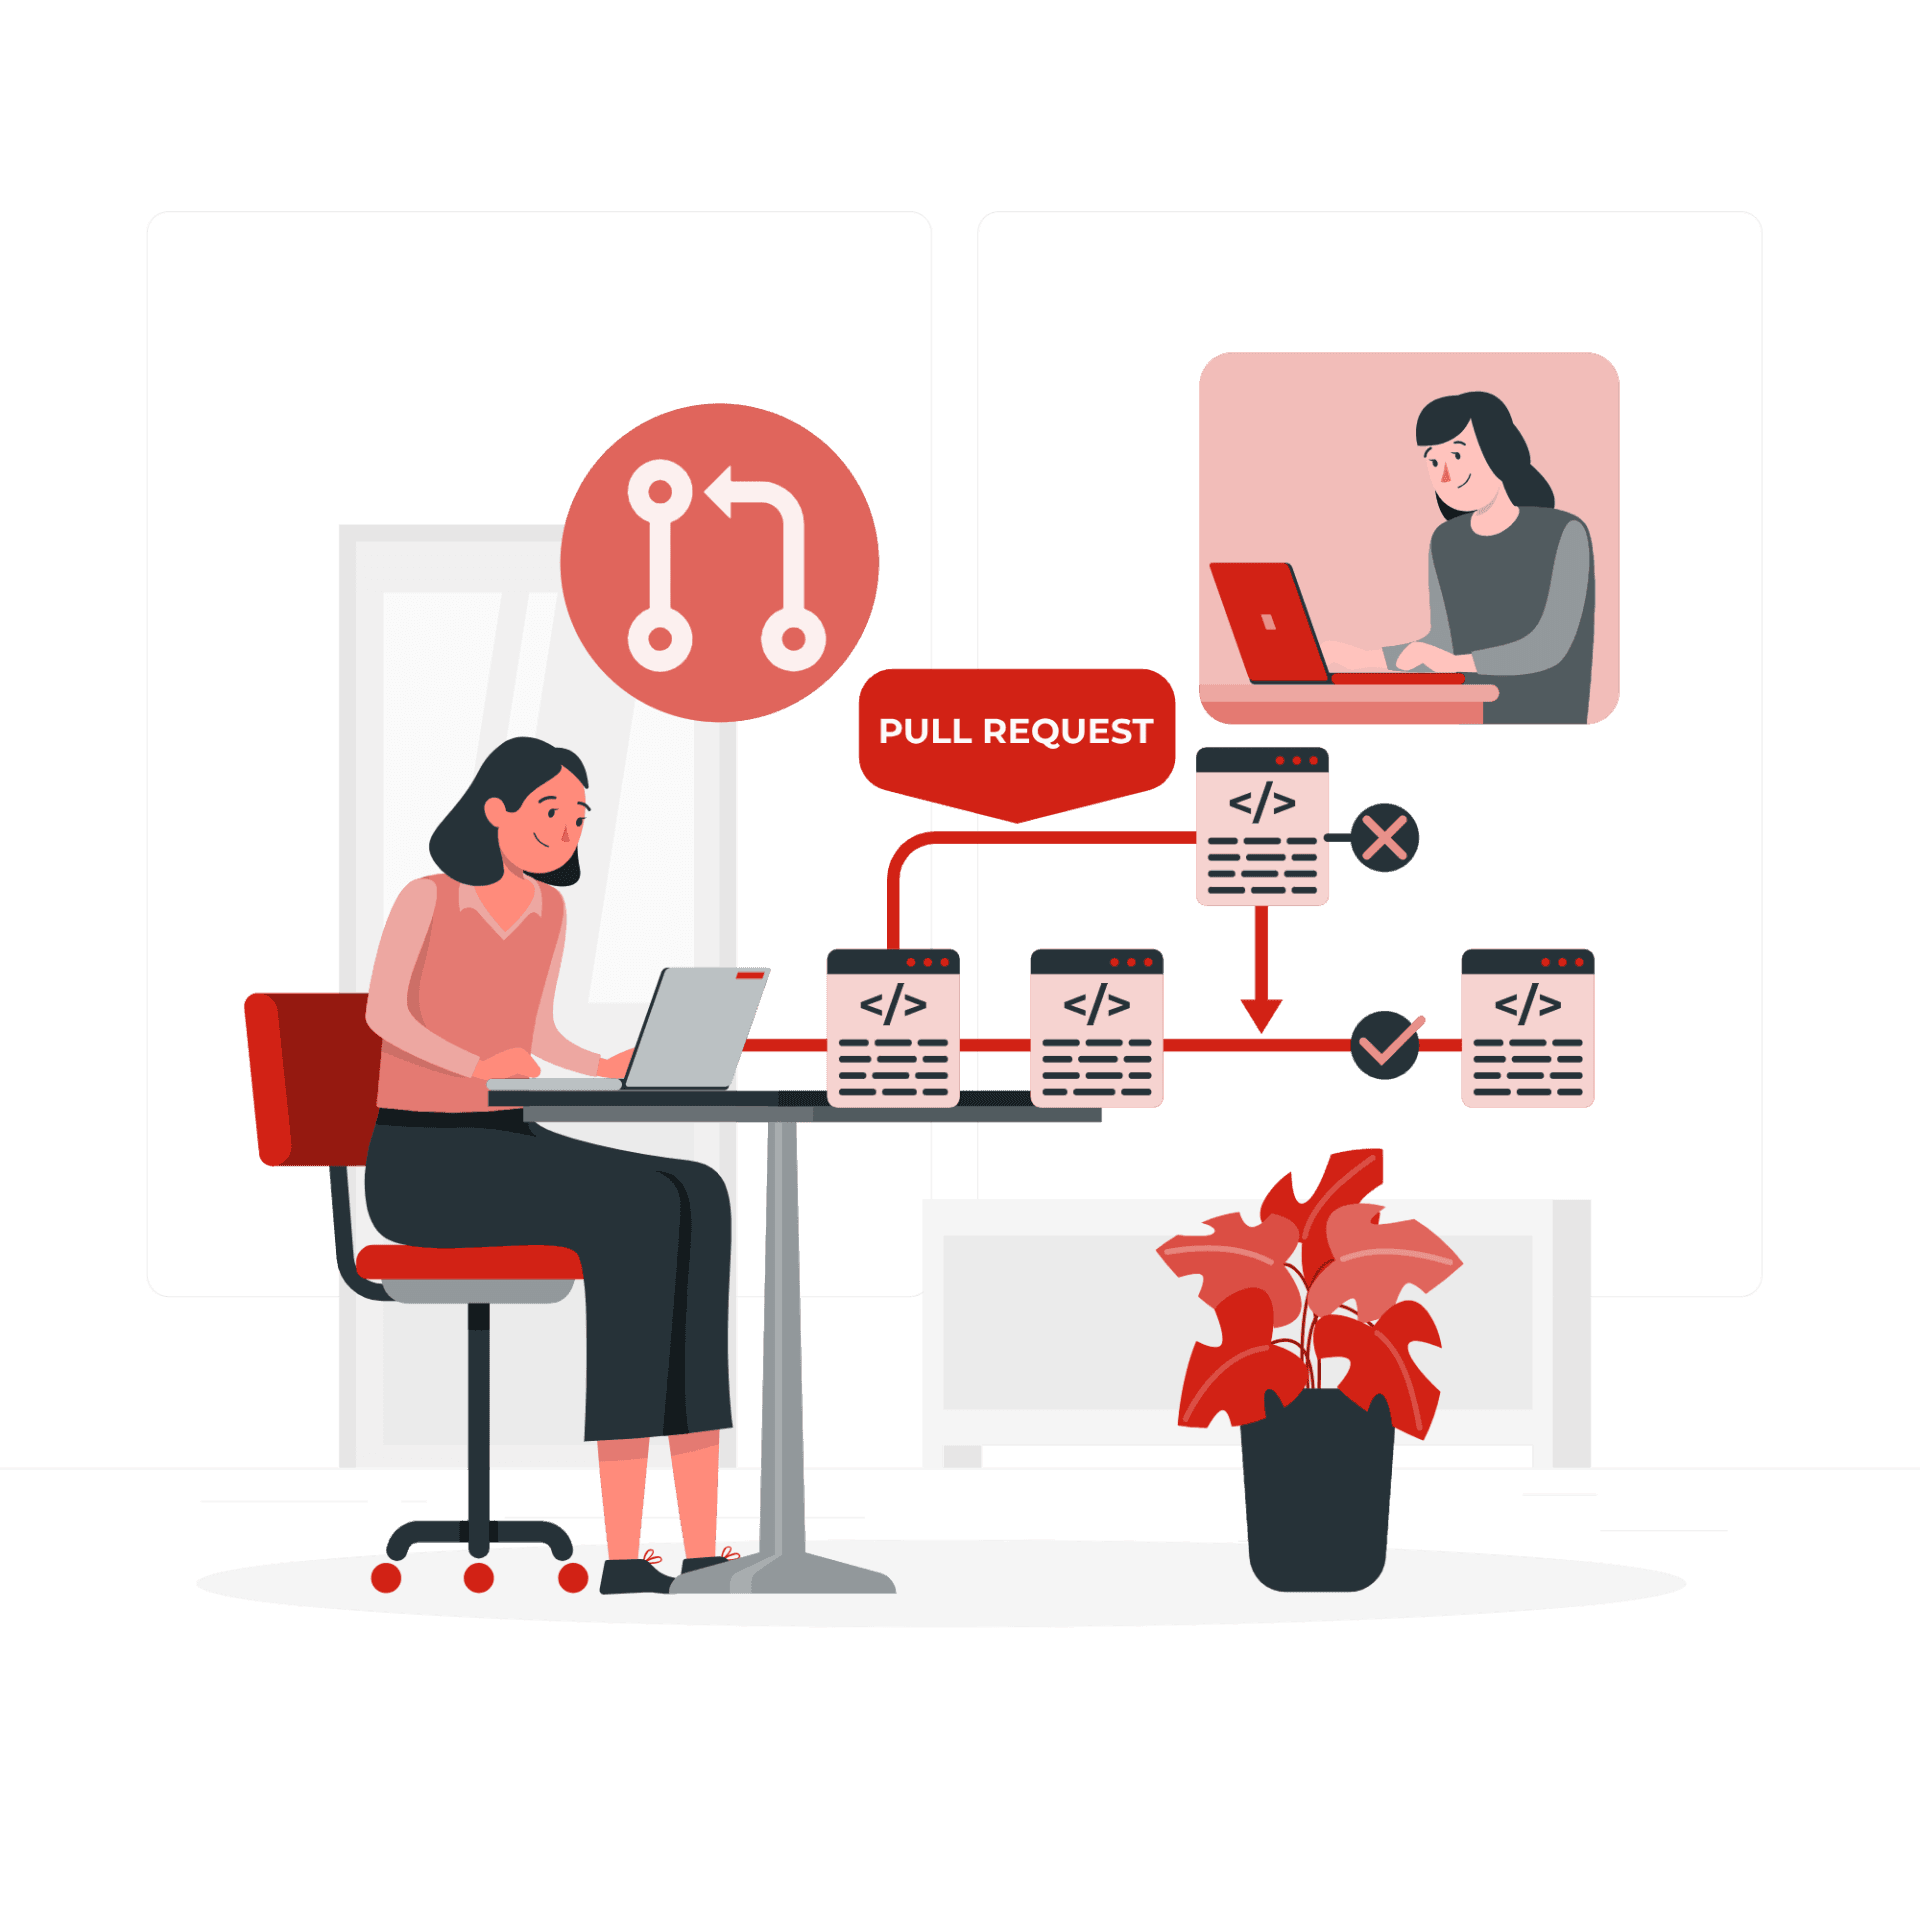
The faster AI writes code, the more review matters. Four layers: diffs for logic (boundaries, errors, concurrency — plus auth, payments, SQL, encryption, secrets), runtime for behavior (type checks, lint, security scans go green first), AI for first-pass screening (a second model reviews, humans read only flagged parts), humans for the final call (AI never clicks merge). Includes commit norms, PR template, branch protection, rollback plans.
Reported by InfoQ on October 3: a GPT-4 coding agent given CVE descriptions successfully exploited 87% of 15 test vulnerabilities, versus 7% without descriptions. rclone's author received 40+ security disclosures in a single month — more than the project's previous decade combined; QEMU has shortened its embargo period. The vulnerability disclosure timeline is collapsing under agent speed.