Don't Let the Agent Demolish Your Old House: 5 Rules for Gradual Legacy Refactoring
The biggest risk of letting an agent refactor legacy code isn't wrong code — it's deleted correct code carrying hard-won lessons. Five rules: build the safety net first, slice rollback-small, make the agent an archaeologist, freeze behavior not implementation, and write down tacit knowledge. Plus a rewrite-vs-refactor framework.
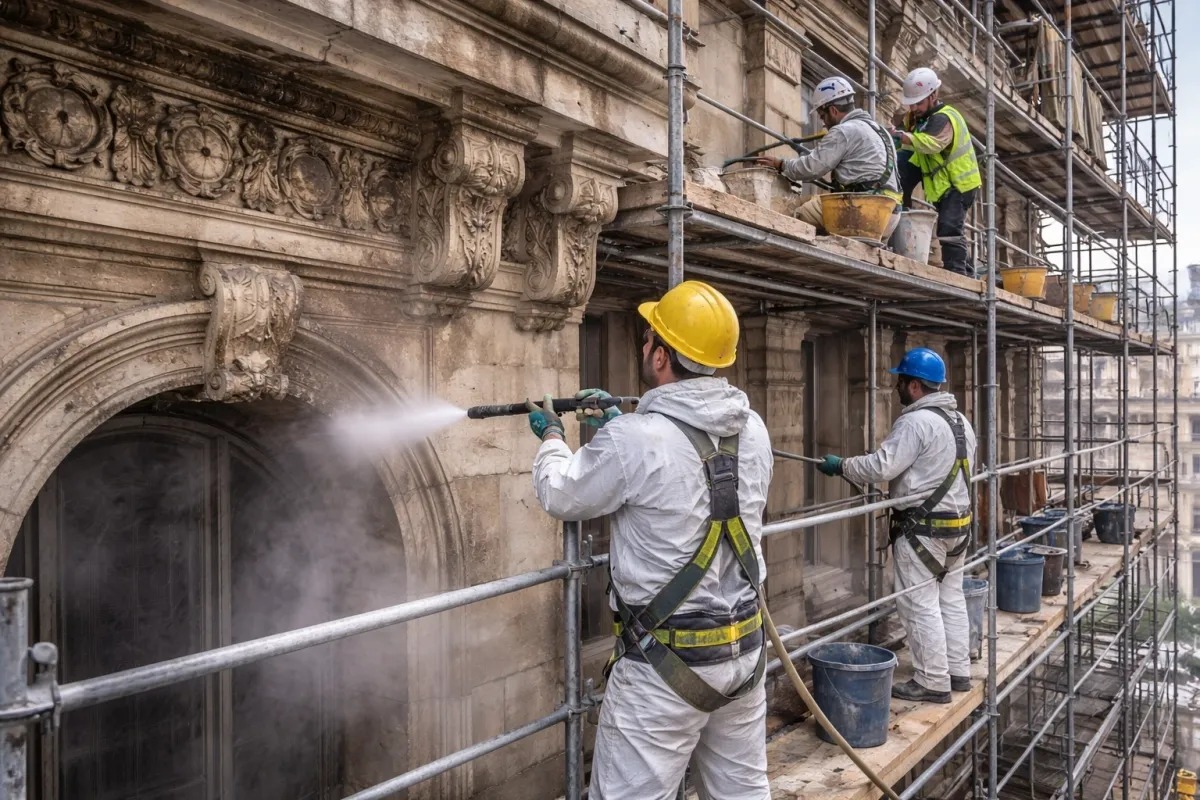
The brutal truth: the agent knows nothing about your legacy code
The most valuable part of legacy code isn't in the code. Why is this if nested three deep? Why is the field called status2? Why can't we deploy on Tuesday nights? The answers live in a git commit message from five years ago, in a departed colleague's head, in the postmortem of some long-ago outage — anywhere but the code.
And the agent can only see the code. What it can't see, it fills in with "reasonable guesses." Reasonable guesses are efficiency on a greenfield project; on legacy code, they're incidents. That redundant-looking null check might have been bought with a P0 outage three years ago; that "obviously deletable" compatibility shim might be holding up a major client's old version.
My core judgment: the biggest risk of letting an agent refactor legacy code isn't code it writes wrong — it's correct code it deletes, the kind that looks redundant but carries hard-won lessons. Once you accept that, the five rules below all follow naturally.
Rule 1: Build the safety net before the agent touches anything
The order is non-negotiable. The net has three layers, and none is optional:
- Behavioral baseline: first have the agent get the existing system running and record inputs and outputs along the critical paths — snapshots, recorded production traffic, whatever works. This is your control group: anywhere the refactored version diverges is where the problem is.
- Critical-path tests: no tests? Write them. How many? Enough to cover the core business flows — not 100%. Let the agent help write the tests, but you define the assertions — agent-defined assertions often just rubber-stamp the status quo, which tests nothing.
- A "state of the module" brief: before any code changes, have the agent produce a document — what this module does, who depends on it, known pitfalls. Reviewing that document is how tacit knowledge becomes explicit. The document itself is the first return on the refactor.
One-line discipline: the agent's first code change happens after the safety net is up. Before that, it may read, never write. A read-only agent can't cause damage; only a writing agent needs supervision.
Rule 2: Slice work so small it can be rolled back
The number-one killer of legacy refactors: changing too much at once, so when something breaks you can't tell which cut caused it. Legacy dependency graphs are webs — you think you touched one function, but you rattled three call chains.
The slicing bar is concrete: every change independent, individually revertable, verifiable within half a day. One module, one layer, one concern at a time. If a PR mixes refactoring with behavior tweaks, the slice is too big — split it.
The heavy weapon is the strangler pattern: old and new implementations coexist, switched by flag or routing, observed for a while before the old one is retired. It sounds clumsy, but it's the only refactor with one-click rollback. For legacy code, rollback-ability beats everything — because you never know what's buried under which stone.
Companion discipline: one concern per PR, and the PR description states the rollback plan. A PR whose rollback plan you can't write is a slice that's too big — send it back for re-slicing.
Rule 3: Make the agent an archaeologist, not a demolition crew
Change the role you assign the agent. Don't say "refactor this module" — say "analyze this module first: where is it called, who would a change affect, what are you unsure about." The former is a demolition crew; the latter is an archaeologist — and legacy code needs the latter.
Mandate three deliverables before any edits: blast-radius analysis + risk list + open questions. You sign off, then it moves. In this order, the agent's hallucinations surface before the edits, not after the outage.
One more hard move: require every change to carry one sentence on "why this change is safe." It's written for you, and for the agent itself — forcing the reasoning into the open is kryptonite for hallucination. A change that can't explain its own safety is an unsafe change.
The red line: the moment the agent says "this code looks unused, I deleted it" — stop it cold. The authority to delete code stays with the human, always. That's the one vote that can't be delegated in a refactor.
Rule 4: Freeze behavior, not implementation
The definition of refactoring is one sentence: improving internal structure without changing external behavior. Turn that sentence into the acceptance bar: after the refactor, every baseline from Rule 1 must pass, without exception.
Differential runs are the hardest evidence: same input, old and new implementations agree on output — that's a pass. "Logically equivalent, trust me" is not a pass; matching outputs are.
Beware the "while I'm at it" optimization: the agent's favorite move during a refactor is tidying business logic on the side — merging three ifs into one, renaming magic numbers, deleting "redundant" branches. Every side quest walks outside the safety net. Discipline: any behavior change in a refactor PR gets rejected on sight. Want to optimize? Open a separate PR through the normal review process. Refactoring and optimizing are two jobs; mixing them means when something breaks, neither side can explain it.
Rule 5: Write the tacit knowledge down
A refactor is the best tacit-knowledge mining opportunity you'll ever get — you're being forced to understand every line. Don't waste it. Every pitfall you hit produces two artifacts: a regression test + a line of documentation (what the pit was, why it exists, how to avoid it). Tests prevent recurrence; docs prevent amnesia.
Leave an epitaph when you're done: the module's known-pitfall list, tech-debt inventory, "do not touch this" list. The next person (probably you in three months) will be grateful. Legacy code is scary not because it's old, but because it's silent — nobody knows why it looks the way it does.
The test of whether a refactor actually succeeded: if docs and tests didn't grow at all, you probably just moved code around without lowering maintenance cost. Prettier code is worthless; knowledge made transparent is what's valuable.
When to rewrite instead: an honest framework
Conclusion first: a rewrite is rarely the right answer. "Burn it down and start over" feels great, but you're not rewriting code — you're rewriting the business rules sedimented in it, the very rules you haven't fully understood yet. The biggest risk of a rewrite isn't the workload; it's re-implementing misunderstood rules incorrectly, a second time.
Three signals that make a rewrite worth serious consideration — all three must hold:
- Nobody can explain the core business rules anymore, and test coverage is near zero — at this point refactoring is as risky as rewriting, so there's no safety premium in keeping the old code;
- The stack itself has become a hiring, deployment, and dependency problem — it's not ugly code, it's a dead ecosystem, and keeping it is slow bleeding;
- You can run old and new systems side by side for differential verification — without this, a rewrite is a naked leap, and 99% of them die at launch.
If you don't have all three, the strangler pattern is the middle path: no rewrite, no head-on assault — replace it one module at a time. Slow, but you arrive alive. The ultimate goal of refactoring was never prettier code — it's moving knowledge out of the code into docs and tests, making it maintainable from then on. Do that, and the old house is renovated without ever collapsing once.
Related articles
The faster AI writes code, the more review matters. Four layers: diffs for logic (boundaries, errors, concurrency — plus auth, payments, SQL, encryption, secrets), runtime for behavior (type checks, lint, security scans go green first), AI for first-pass screening (a second model reviews, humans read only flagged parts), humans for the final call (AI never clicks merge). Includes commit norms, PR template, branch protection, rollback plans.
Prompts in vibe projects live in code strings, admin text boxes, and docs — changed live, version unknown when things break. This guide shows how to treat prompts like code: a prompts/ layout, YAML frontmatter, semantic versioning, PR reviews, canary rollouts with one-click rollback, plus an evals baseline — and a real war story: one added sentence cost 12 points of classification accuracy.
Cloudflare's Birthday Week blog makes the case plainly: GitHub was designed for humans writing code; the agent era needs the collaboration layer reinvented. Artifacts enters open beta with a repo for every agent, plus a developer competition — $25,000 in credits for first place, deadline October 14. This is the first time a major infra vendor has put 'infrastructure for agents writing code' on the table as a public proposition.