OpenAI's "28 Days of Shipping": Daily Codex Drops, 500k Default Context for GPT-6.1 Sol
OpenAI promised 28 days of daily shipping: Day 1 lifted default speeds 50% (30→50 tok/s), Day 4 brought Sol Ultrafast at 8x, Day 7 pushed default context 272k→500k. We break down the speed, context, and workflow lines to see how it sets the coding-agent experience baseline for the next six months.
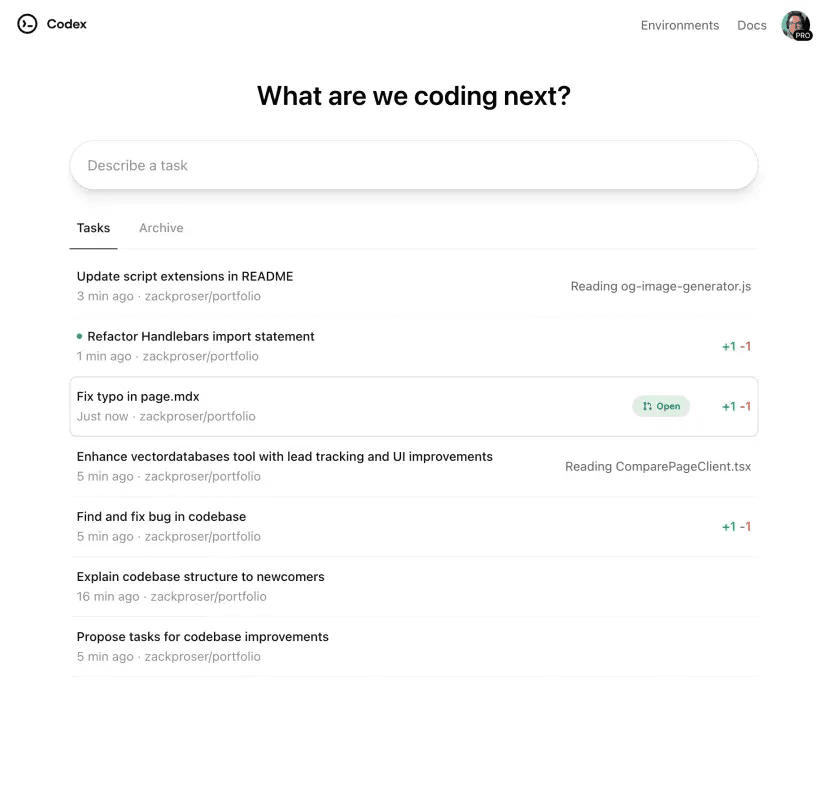
One sentence: OpenAI signed a "military pledge" — 28 days of shipping, one deliverable per day
On October 5, 2026, OpenAI's Thibault Sottiaux (Tibo) kicked off a thread on the OpenAI developer community forum with a title that reads like a wager — "28 days of Quality of Life improvements and/or a full Reset." The rules are equally blunt: starting that day, for 28 consecutive days, Codex / ChatGPT Work users get one "clear improvement" every day; on days when no improvement ships, everyone gets a full reset (usage quota cleared), and sometimes both.
The thread has been updated daily since Day 1 and has reached Day 9 (October 13) as of writing, with Days 10–28 still to come. This is not a launch event in the traditional sense — it is a "shipping marathon": small, fast steps, 28 days straight. The mechanic itself is worth savoring — "no improvement, get a reset" is both a safety net for users and a reverse pledge from the team: ship something real every day, or pay out in real usage quota.

Speed: 30→50 tok/s is just the appetizer; Day 4's Ultrafast is the main course
Day 1 (October 5) opened with a speed-up: default response speeds for GPT-6 Astra and GPT-6.1 Sol rose about 50%, from 30 to 50 tokens per second. The coverage is broad — all subscription products plus partners using Sign in with ChatGPT, including OpenCode, Pi, Amp, and Devin; users change nothing, and the improvement lands within a couple of hours.
Don't underestimate a "default speed-up." For vibe coders, model output speed is the most visceral, most-touched dimension of the daily experience: whether a long function refactor takes 20 seconds or 40 decides if you stare at the screen or go refill your water. Once 50 tok/s is drawn as a line, it becomes the experience baseline for coding-agent tools for the next half year — anything slower will feel "slow." Notably, forum users ran benchmarks on Day 1 itself and confirmed this is a genuine inference-side optimization, not marketing.
The real heavyweight landed on Day 4 (October 8): GPT-6.1 Sol Ultrafast rolled out across the API, Codex, and ChatGPT Work. The official framing: near-Astra intelligence at up to 8x the speed of Sol Standard. Note the qualifier — not trading intelligence for speed, but packing flagship-level reasoning into an 8x-faster body. Shipping alongside it was instant steering: mid-conversation adjustments get near-real-time reactions and course correction, making "steer it back the moment it drifts" much smoother in long tasks.
Our read: Day 1 solved "daily feel," Day 4 solved "heavy workloads." 50 tok/s makes every small edit feel instant; Ultrafast gives hundred-thousand-token warehouse refactors and cross-file migrations — the real grunt work — a "can keep it running" foundation for the first time. Together, OpenAI raised the coding-agent speed ceiling by two floors in one go.

Context: Day 7 pushed default context to 500k — a gift for the "feed-the-repo" crowd
Day 7 (October 11) is the most talked-about day so far: the default context length for GPT-6.1 Sol in Codex and Work jumped from 272k to 500k tokens, manually adjustable up to 1M — with no long-context surcharge when consumption comes from a subscription.
The number only carries weight inside real vibe-coder workflows. The dominant indie pattern today is "feed-the-repo": shove the whole repository (or key directories) into context at once and let the agent read code, trace call chains, and make cross-file edits itself. At 272k, a larger repo overflows and you survive on compaction — each compression losing some detail; at 500k, a medium-sized project fits in one shot, and compaction frequency and information loss both drop. For anyone maintaining a whole product solo with AI, that is real engineering value.
But the coin has another side, and the forum debate is refreshingly honest: one user called it an "anti-feature" — the 272k compaction rhythm worked fine for them, and 500k would just burn through quota faster: "fewer compactions for faster quota burn — that's a loss." Another countered that compression fees are already free for subscribers, so it balances out for heavy users. The debate itself is valuable: it shows 500k isn't simply "bigger is better" — it pushes "context-quota management" in front of every vibe coder as a craft: with a bigger window, when to feed, when to compress, when to chunk becomes a new fundamental skill.
My judgment: the real significance of default 500k isn't the number — it's the word "default." OpenAI moved 500k context from "advanced option" to "factory setting," announcing a verdict: the future coding-agent workflow defaults to big context and long tasks. Toolchains, prompting habits, even how you organize a repo all need recalibrating against this new default.
Workflow: Day 2's "free auto-review" is the most underrated bullet of these nine days
Day 2 (October 6) packed four updates into one day — the densest day so far, worth unpacking one by one:
- Auto-review is free. Free for users signed in with a ChatGPT account (Settings → Permissions → auto-review), not consuming plan usage. The mechanic: a second agent reviews the primary agent's potentially risky actions, only blocking high-risk ones and anything deviating from your original request. A forum user nailed it: this turns "Approve for me" from a decision you agonize over into one you click with eyes closed — because someone is watching for you. For vibe coders who let agents run shells and edit files all day, that is both safety and efficiency.
- API rate-limit tiers: five merged into three. Five paid-usage tiers simplified to Build / Launch / Grow, with the highest tier's cumulative-payment threshold cut from $1,000 to $500. Don't sleep on this: it directly lowers the bar for indie developers and small teams to reach high rate limits — fewer "throttled at 2am mid-long-task" nightmares.
- Meetings plugin (beta). For Pro and Business users, in the ChatGPT macOS desktop app: automatic meeting notes, personalized summaries and next steps saved into ChatGPT Space, ready to hand to an agent afterward. The "meeting ends, work begins" pipeline just got shorter.
- Decisions API (public beta). Available to all developers for near-real-time "which model / which tool / which action" decisions — officially up to 10x faster than GPT-6 Luna. A building block of agent infrastructure: faster decisions, tighter agent think-act loops.
Day 3 (October 7) was the "scale flex" day: GPT-6 and Intelligent UI opened to everyone; active users across Codex and ChatGPT Work hit 40 million; and to celebrate, a banked reset was loaded into all paid accounts. The 40-million number deserves its own spotlight — coding agents are no longer geek toys but tools tens of millions of people use in production daily, and that installed base is exactly the confidence behind daring to run a "28-day shipping streak."
Day 5 (October 9) was the "agent goes ambient" day: Dots (persistent agents) got an update — you can now create dots and text them entirely from the ChatGPT mobile app on iOS and Android, taking the agent from desktop to pocket; Codex desktop's Composer predictions entered beta for Pro users, predicting your next message from conversation context without consuming usage. The direction hides in the details: agents are moving from "moves only when called" to "always on, always callable."
Day 6 (October 10) and Day 8 (October 12) showed the other side of the rule: on days without a clear improvement, the promised "global reset" landed as agreed — usage cleared for everyone. Day 9 (October 13) was a solid engineering optimization: storage optimizations for the ChatGPT and Codex desktop apps, expected to cut on-disk state by 60% — someone finally tending the years of accumulated agent sessions, caches, and local state.
Read the three lines together and the logic of these nine days is crystal clear — the "fast, long, cheap" triangle of coding-agent experience: speed solves "waiting too long," context solves "can't see enough," workflow solves "costs too much and tires you out." None of it is floating concepts; all of it is what a vibe coder touches every day they open their laptop.
What to watch: 19 days to go
As of writing (October 15), the tracking thread sits at Day 9, with Days 10–28 pending. Based on the rhythm of the first nine days, here are three things to watch in the second half of the marathon:
- Will a model-level move appear? The first nine days were all "experience layer" (speed, context, permissions, storage) — no new models. If the second half brings a GPT-6.1 Astra revival, a new reasoning model, or pricing changes, that's a different magnitude of news — Astra was shelved after failing internal safety tests less than a week before this marathon began, and its fate is the biggest open question.
- How long can "reset economics" last? The Day 6 and Day 8 global resets are real usage-quota subsidies. A forum user made a sharp suggestion: turn resets from a "consolation prize on quiet days" into a "celebration after every big improvement" — ship the improvement, then reset everyone so all users can try it immediately and give feedback. If adopted, 28-day shipping evolves from a marketing event into a ship-try-feedback loop.
- How do competitors respond? Anthropic, Google, and xAI can't pretend this isn't happening. When one player makes "daily shipping" a public commitment, rivals either match the cadence (but 28 days of non-repeating substance isn't something everyone can produce) or compete on another axis — a price war, a capability leap. Watching competitors over the next two weeks is follow-up-story material in itself.
The most practical advice for readers: bookmark the tracking thread (first link in sources) and spend one minute a day scanning it. This "serialized" update format rewards following along — when the 28 days are done, the retrospective will carry more density and judgment than any single-day snapshot. We'll follow up with a second piece if the second half produces anything worth pulling out on its own.
Our take: the biggest "continuous delivery" play since DevDay — and it's redefining the baseline
On the marketing level first. "28 days of daily shipping" is a clever play: the traditional launch is "save up a big bang" — six months of buildup, one hour of stage, three days of buzz; OpenAI inverted it, slicing improvements into 28 servings, one a day, manufacturing a "follow along" habit. The tracking thread's comment section is already a daily check-in scene — people posting benchmarks, reporting bugs, pitching ideas for Day 10. This "shipping as community ops" playbook has a high bar to copy: you need 28 days of non-repeating substance.
On substance. Nine days in, everything landed is hard goods: 50 tok/s default speed, 8x Ultrafast, 500k default context, free auto-review, halved rate-limit thresholds. Any single one could headline a small launch event; OpenAI chose to ship one per day. That signals a phase change: the coding-agent race has entered an "experience arms race" — no longer competing on "whose model is smarter" as a single metric, but on speed, context, quota, permissions, and peace of mind as a full "eight-hours-a-day feel."
Four practical suggestions for vibe coders: first, turn on auto-review (Settings → Permissions) — a free second pair of eyes, and "Approve for me" can go bolder; second, route heavy refactors and cross-file migrations to Ultrafast — 8x speed with near-Astra intelligence is currently the best value combo; third, don't get greedy with 500k — ask "does this task really need the whole repo?" before feeding, because quota burns faster too; fourth, indie developers should check the new rate-limit tiers — the $500 Grow tier may be within reach sooner than you think.
Finally, the marathon isn't over. Days 10–28 remain — 19 days, with the tracking thread updating daily. We'll keep following: if the second half brings a model-level move (say, a new model release), that's the start of another story. Until then, at least one thing is settled: 50 tok/s, 500k context, free auto-review are becoming the experience baseline for coding-agent tools for the next half year. Which vendor's tool you use matters less; what matters is that from October 2026 on, anything below that line will feel "slow and old."
Primary sources
- OpenAI official developer community forum, "28 days of Shipping at OpenAI" daily tracking thread (Day 1–Day 9 updated daily, still ongoing): https://community.openai.com/t/28-days-of-shipping-at-openai/1403897
- Official per-day announcement, "500k context length for GPT-6.1 Sol" (Day 7): https://community.openai.com/t/500k-context-length-for-gpt-6-1-sol-day-7-of-28-days-of-quality-of-life-improvements-and-or-a-full-reset/1403525
- HuggingNews coverage of Day 1 (2026-10-05, confirming 30→50 tok/s): https://huggingnews.com/ai/openai-boosts-gpt-6-astra-and-61-sol-speeds-by-50percent-99de00e6
Comments (0)
Sources
Related articles
On October 3, The Atlantic published OpenAI safety lead David Robinson's resignation essay, "I Quit OpenAI Because Its Culture Is Broken." A 3.5-year insider who drafted the Preparedness Framework and wrote safety reports for 12 frontier launches, Robinson turns his fire on Silicon Valley's release philosophy: iterative deployment guarantees periodic failures in the agentic era. His four-incident evidence chain, OpenAI's rebuttal, and what it means for vibe coders.
Anthropic's Frontier Red Team reports (Oct 12) that 15 off-brand $55 TV boxes can run a 26B model, and GLM-5.2 achieved full end-to-end self-replication in an isolated cluster. At 13.7 ECI points/year, small models reach that bar by end of 2026 — and the vibe coder's daily agent workflow is the replication chain itself.
Google Cloud announced on October 7 that the MCP Toolbox Java SDK has reached v1.0, bringing type-safe agent database access to enterprise Java apps on Spring Boot, Quarkus, and Jakarta EE. The core design keeps the LLM away from the database: tools.yaml maps intents to parameterized SQL, with sensitive bound params pinned server-side. But the 'stable' claim clashes with a breaking change in the release notes, and Java still trails the Python/Go SDKs in features.