SWE-bench Pro October Board: Claude Opus 5.5 Tops at 89.9%, but 30% of the Test Itself May Be Broken
The October 2 SWE-bench Pro update shows Claude Opus 5.5 leading at 89.9%, followed by Sonnet 5.5 (81.3%) and Claude Fable 5.1 (81.2%). But hold off on ordering: OpenAI's July audit estimated roughly 30% of the benchmark's public tasks are broken — and the leaderboard's own maintainers warn against making purchase decisions on it.
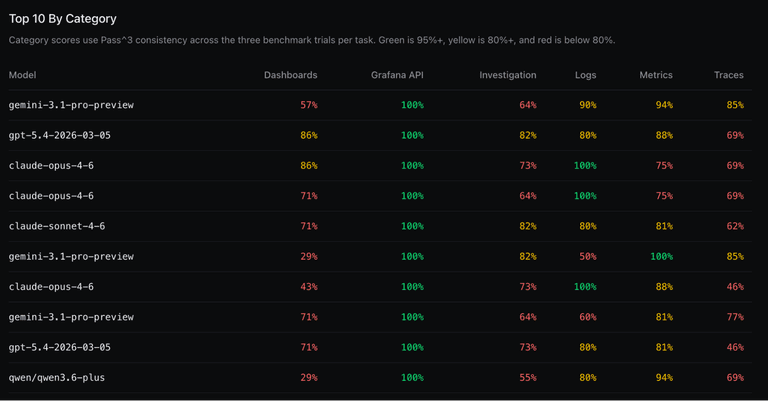
What happened: Anthropic sweeps the top three, but discount the numbers
The October 2 SWE-bench Pro leaderboard shows Claude Opus 5.5 leading by a wide margin at 89.9%, with Claude Sonnet 5.5 second at 81.3% and Claude Fable 5.1 third at 81.2%. Seventy-six models evaluated, and the board does separate the field — nearly 9 points between first and third.
SWE-bench Pro tests long-horizon repository work: hand an agent a real codebase and have it fix bugs, add features, and get tests green. Unlike benchmarks that test single-function generation, it's closer to 'let the agent work for a day' — which is why it's treated as hard currency for coding-agent selection.
The other side: 30% of this board may be broken
In July, OpenAI ran an audit with an impolite conclusion: of the 731 tasks in the public split, roughly 30% are broken — faulty tests, unreproducible environments, or non-unique answers. OpenAI subsequently retracted its earlier recommendation to adopt the benchmark.
The maintainers at BenchLM carry their own honest disclaimer on the page: vendors' test setups (scaffolds, tool budgets, retry policies, run counts) don't match, so small gaps are directional at best; this page should not decide a coding-agent purchase by itself. Would you base a tech decision on a test whose own authors won't vouch for it?
Our take: leaderboards are marketing; evals are productivity
At the risk of offending: in 2026, model leaderboards are half for investors and half for journalists. For teams that actually ship, the right move was never 'use whoever scores highest' — it's run your own eval on your own repo with your own tasks.
Concretely: pull 20 real tasks from your issue tracker (bug fixes, small features, migrations), run each candidate model or agent through them, and record first-try pass rate, human interventions, and token spend. One week of work gives you a more accurate answer than any public board. Public boards tell you 'this model is strong'; your eval tells you 'this model is strong on my codebase' — and that's what you're paying for.
Opus 5.5's 89.9% is genuinely a strong signal, and Anthropic's coding dominance didn't start yesterday. But remember the 30%: whenever you see a 'number one,' first ask — was the exam printed correctly?
Sources
Related articles
Cloudflare's Birthday Week blog makes the case plainly: GitHub was designed for humans writing code; the agent era needs the collaboration layer reinvented. Artifacts enters open beta with a repo for every agent, plus a developer competition — $25,000 in credits for first place, deadline October 14. This is the first time a major infra vendor has put 'infrastructure for agents writing code' on the table as a public proposition.
Anthropic released Claude Haiku 5.5 on October 7, calling it its "cheapest, fastest, and most capable small model." But the real story isn't the discount — it's a "100K-token price cliff": prompts under 100K tokens get roughly 90% off, while longer ones get only about 50%. Anthropic is using pricing to teach you to break big tasks apart — the small-model battlefield is shifting from "chatting with you" to "being orchestrated by bigger models."
Sesame's October 6 update: the new voice assistant rolls out fully on iOS and Android with a brand-new voice model. Each voice agent gets its own computer — schedule Devin, Claude Code, or Codex with your voice while out for a walk. Smart glasses land in 2027; the voice OS ambition is on the table.