Offline-First That Actually Works: A Local-First Architecture Playbook for Vibe-Coded Projects
AI tools default to cloud-first: no signal, white screen. This playbook shows indie developers how to convert a vibe-coded project to local-first — a 4-question decision flow, sync-engine matrix, six rollout steps, five anti-patterns, and an offline test checklist.
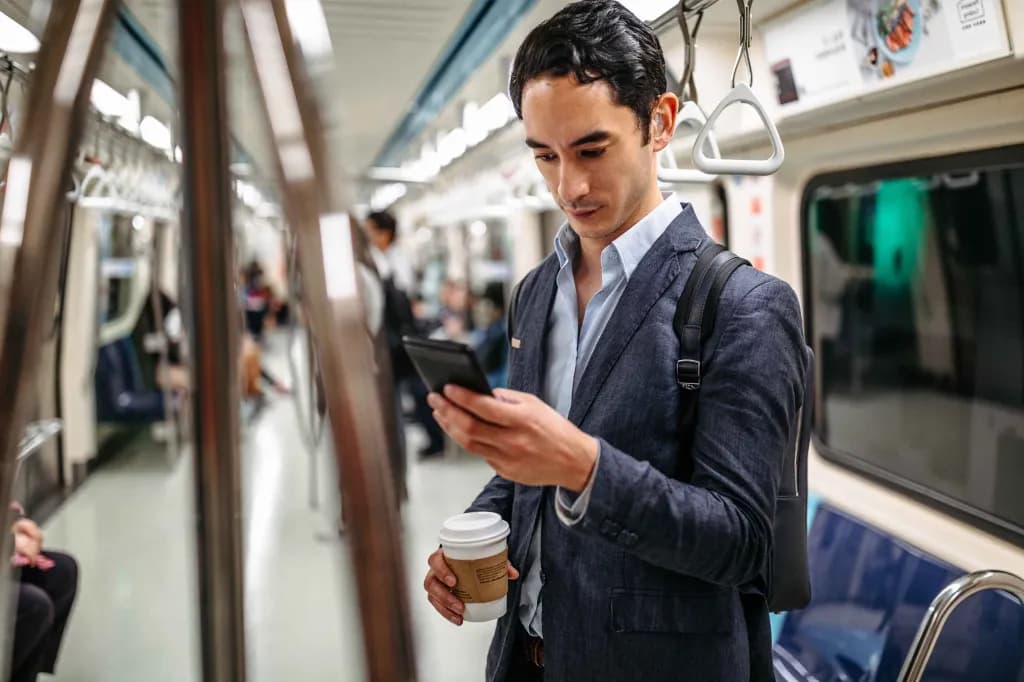
It starts on a morning with no signal
Picture this: you spent three evenings vibe-coding an expense tracker with Claude Code. Beautiful UI, smart categories, silky charts. You send it to a friend to try. Next morning, during rush hour, your friend opens it in the subway — the signal flickers in the tunnel, the app hangs on a loading spinner for ten seconds, then throws a cold "Failed to fetch." They close it and never open it again.
This isn't bad code. It's the wrong architecture. AI coding tools default to "cloud-first": your UI is just a mirror of a cloud database, and the moment the server behind the mirror goes dark, the mirror shatters. And your users — commuters, travelers, overseas users, people on factory floors — live large parts of their lives in weak or nonexistent connectivity.
Local-first is the architecture built to cure exactly this: the local database becomes the "source of truth" for your data, and the cloud is demoted to a sync replica. Online or offline, the app works exactly the same; when the network returns, data quietly converges. This article skips the theory and covers how an indie developer actually ships it in a vibe-coded project: whether you should adopt it, which engine to pick, the six steps, and the five pitfalls to avoid at all costs.
The core judgment up front: local-first is not "adding a cache." It is an architectural oath — from now on, your UI talks only to the local database and never waits on the network. If you can't accept that rule, don't adopt it. A half-adopted local-first is more painful than none at all.
What local-first actually is, in three sentences
Sentence one: the local database is the source of truth. Every read and write hits local storage first; the UI always reads locally, so rendering is memory-fast and offline is a non-event.
Sentence two: the cloud is a sync replica, not the master. When the network is available, a sync engine pushes local changes up and pulls remote changes down in the background. Sync is "eventually consistent," not "realtime strongly consistent."
Sentence three: conflicts are normal, not exceptional. The same todo edited on a phone and a laptop simultaneously needs a pre-decided rule for which version wins — not an error dialog asking the user to choose (users can't choose, and don't want to).
This is fundamentally different from the familiar "offline-mode patch": patch-style offline is a bandage on a cloud-first architecture — a loading cache here, a retry there, a "you're offline" banner — while large parts of the app go dead without connectivity. Local-first is the foundation: with no network, the app is 100% usable; only syncing pauses. Bandages stop bleeding; they don't hold up buildings.
What the standard three layers look like
UI layer → local database (SQLite / IndexedDB) → sync engine → cloud database. Note the direction of the arrows: the UI never touches the network directly; every byte in or out passes through the sync engine's single gate. Many vibe projects fail exactly here — the agent quietly opens a backdoor, a page calls the cloud API directly "to be fast," and on disconnect only that page goes white. It takes a week to find.
Should you adopt it? Four questions, stop at the first "no"
Local-first is heavy architecture. Don't adopt architecture for architecture's sake. Answer these four in order; stop at the first "no":

Question 1: Will users use it with no or weak connectivity?
Subways, airplanes, elevators, overseas roaming, factory floors, mountains — if your core scenario touches any of these, the answer is "yes." Counter-example: a purely desktop-internal data dashboard whose users always sit on the corporate LAN — adopting local-first there is pure self-inflicted drama. Be honest: for most consumer-facing vibe projects, this question is a "yes."
Question 2: Is the data mostly private to the user, read and written on one device?
Expense trackers, notes, todos, fitness logs, personal knowledge bases — classic "yes," the sweet spot for local-first. If your app is heavily multi-user collaborative (several people editing the same canvas simultaneously, a ride-hailing dispatch board), conflicts go from "occasional" to "daily," and sync-engine complexity will eat all your time. The more honest choice then: ship an offline read cache first, keep writes on the cloud, and leave realtime collaboration to purpose-built solutions.
Question 3: Is the data volume and table count manageable?
Rule of thumb: tens of megabytes per user and fewer than ~20 tables is a maintenance load one person can carry. Beyond that, don't go all-in at once — phase it: make the 3–5 core tables offline first, keep the rest on the cloud. Migrating everything in one shot is the most common way indie developers die: three months later you realize you're maintaining a homemade distributed database instead of building a product.
Question 4: Can you accept that "sync" is a permanent maintenance item?
This is the one that stings. Shipping is just the beginning; every schema change, every conflict-rule tweak, every tombstone GC policy afterward is your job. Local-first moves the complexity of "the network is unreliable" from the user's side to the developer's side — the user is happy, you pay the debt. If you're solo and haven't validated PMF yet, the compromise is perfectly respectable: offline reads + a write retry queue gets you 70% of the perceived benefit at 20% of the cost.
One-line summary: frequent weak-connectivity scenarios + small private datasets + willingness to service the debt = adopt. Missing any one of them, take the compromise routes on the right side of the flowchart. No shame in it.
Picking your stack: the sync-engine matrix and local storage
This is the most bookmark-worthy section. In 2026 you should not build your own sync engine (seriously, don't). Pick from these:
| Engine | Backend binding | Conflict resolution | Learning curve | Best for |
|---|---|---|---|---|
| ElectricSQL | Postgres | Automatic CRDT merge | Medium | Projects that already run Postgres and want incremental adoption |
| PowerSync | Postgres / MySQL / Mongo | Server rules + client merge | Low-medium | Mobile-first (Flutter / RN) solo devs who want a ready-made SDK |
| Zero | Built-in (or Postgres) | Server authority + optimistic updates | Medium | React stacks that want sync to "feel like writing local state" |
| Automerge | None (self-hosted sync) | CRDTs, mathematically guaranteed convergence | High | Document/JSON-shaped data, for hackers fine with running their own sync service |
| Yjs | None (self-hosted) | CRDTs, strongest for text collaboration | Medium-high | Rich-text and canvas collaboration (note: a collaboration engine, not a general sync engine) |
| Homemade LWW | Any | last-write-wins by timestamp | Low | Nobody — unless you want to experience data loss firsthand (see anti-pattern #1) |
Recommendations for indie developers, in priority order:
- Already on Postgres: ElectricSQL or PowerSync first. Why: no database switch, the sync layer is incrementally adoptable, and you can roll back if it fails. Trade-off: you must accept its sync semantics (e.g., ElectricSQL's shape-subscription model) — don't try to hand-roll SQL sync around it.
- Starting a new project: follow your frontend stack. React → Zero, Flutter / React Native → PowerSync. Why: SDK maturity directly determines how many potholes you hit; the project's issue tracker is your free QA department. Trade-off: you're locked to one engine and migration is expensive — so read its "what it doesn't support" docs before the "what it can do" page.
- Document/JSON-shaped data: Automerge. Why: CRDTs are a cheat code for document merging — two offline-edited versions converge with a mathematical guarantee and no lost characters. Trade-off: you run your own sync service (or pay for hosted), and relational queries are its weak spot. Don't use it as a database.
How to pick local storage
- Web: SQLite compiled to WASM (wa-sqlite / persistent sql.js builds) is the first choice. Why: real SQL, real transactions, and the SQL migration scripts your agent generates run as-is. IndexedDB (via Dexie) is the backup. Why: simple API, but weak querying — once you have joins everywhere you'll suffer. Trade-off: WASM SQLite adds a few hundred KB to first load; lazy-load it if first paint matters.
- Mobile: native SQLite (expo-sqlite / OP-SQLite). Don't store structured data in AsyncStorage — that's a key-value store, not a database, and in three months your "queries" will be full-table scans.
- The one-line red line: local storage must support transactions. A "database" without transactions will manufacture half-written rows the moment a sync gets interrupted mid-recovery, and you will debug it crying.
A selection constraint you can feed your agent verbatim
The danger in selection isn't picking wrong — it's your agent quietly mixing approaches behind your back. Save this as an AGENTS.md snippet so it gets read before the agent touches the data layer: "This project is local-first: the UI layer is forbidden from calling cloud APIs directly; all data reads and writes go through local SQLite; new tables are local-only by default; tables that need syncing must declare sync=true with a reason in the migration comment; deletions always write tombstones, physical deletes are banned; conflict-resolution policy lives in the README conflict matrix — the agent must not invent its own." Why: an agent's default tendency is "make the feature work fastest," which means calling the cloud directly — this constraint blocks the shortcut and forces it through the front door. Trade-off: you'll spend 10% more time arguing with the agent about "why can't I call it directly," but that 10% buys you an architecture that doesn't rot. Worth it.
Six steps: converting a cloud-first project to local-first
Assume you already have a working vibe-coded project (cloud-first). Here are the six steps to convert it. Each step notes the "why," the cost, and one prompt snippet you can hand to an agent — this kind of conversion splits beautifully into small tasks for agents to run in parallel while you review.
Step 1: Local schema leads, cloud schema follows
From today on, table creation and column changes start as local SQLite migrations; the cloud schema aligns behind the sync engine (or stays compatible). Why: the source of truth lives locally, so the authoritative schema version must live locally — otherwise you drown in "which side's schema wins." Trade-off: you lose the joy of "just tweaking the table in the cloud console" — every structural change goes through a migration file. Slower, but rollback-able. Prompt for your agent: "Generate local SQLite migration v3: add nullable due_date to the todos table, idempotent and rollback-able, and update the TypeScript type definitions to match."
Step 2: Deletions must become tombstones
Physical deletes are banned in local-first. Deleting a row = writing a tombstone ({id, deleted_at}); the sync engine uses tombstones to propagate the deletion to the cloud and other devices, and GC cleans them up after expiry. Why: device A deletes a todo while offline, device B edits the same todo while offline — without tombstones, B's edit "resurrects" the deleted row during sync. That's the #1 paranormal event for local-first beginners. Trade-off: tombstone rows pile up in your tables, so every query needs the where deleted_at is null filter; make "all queries exclude tombstones by default" your agent's first iron rule and check it in every code review.
Step 3: Write down the conflict policy, per table
Don't use one global policy. A sensible default ladder: ① user-private data (note bodies, settings): field-level LWW + keep a conflict copy. Why: losing characters is scarier than a dialog — Google Docs works exactly this way. ② Counter/state data (like counts, order status): server is authoritative; failed optimistic updates roll back. Why: for this data, "wrong" costs more than "lost." ③ Money/permission data: no offline writes, online required. Why: some money you simply don't gamble with — that's a floor, not conservatism. Write this table into your README and make the agent read it before generating any data-layer code.
Step 4: Offline write queue with idempotency
Writes made offline go into a local outbox table and replay in order. Two hard requirements: every operation carries a client-generated idempotency key (UUID); the server dedupes on replay by key. Why: network jitter causes "sent but the ack never arrived" — without idempotency keys you get double charges and duplicate orders. And queue insertion must be atomic with the write. Why: if the app crashes between "local write succeeded" and "enqueued," the data is lost, and you'll misdiagnose it as a sync bug when it's your bug.
Step 5: Decouple auth from the sync channel
An expired token must never cause the sync engine to wipe local data or stop writing. The correct design: the sync channel only moves data; the auth state machine is maintained independently. When the token dies, syncing pauses and local writes continue; after re-login, pushing resumes. Why: the most common vibe-project crash is the agent writing "on 401 → clear local cache and jump to login" into an interceptor — in local-first that means a dropped connection equals lost data. Trade-off: you maintain one extra "pending sync" indicator, but it's worth it — the calm a user feels seeing "3 changes pending sync" is retention.
Step 6: Version migration and old clients
When the schema upgrades, old clients may still write with the old shape. The policy: the sync protocol carries a version number, the cloud keeps N-1 compatible reads for at least one release cycle, and clients do "lazy migration" — upgrading old rows on read and writing them back. Why: indie developers can't force upgrades; users not updating for three months is normal. Trade-off: compatibility code is tech debt — write "remove v3 compat layer in the v5 release" into your roadmap, or it will rot there forever.
Five anti-patterns, each paid for in real money
Anti-pattern #1: last-write-wins by timestamp
Two devices' clocks are never in agreement — seconds of skew is normal, hours (user-changed time, timezone bugs) happen too. Deciding conflicts by updated_at means handing data correctness to luck. Use logical clocks (Lamport timestamps) or hybrid logical clocks instead; if you must use wall-clock time, use it for display ordering only, never as the decider.
Anti-pattern #2: syncing every table
Log tables, analytics tables, temp cache tables all get sync configured — and now the user's phone holds 800MB of analytics events, sync never finishes, and the battery drains visibly. The rule: only data the user would want to see after logging in on a new device enters the sync set. Everything else stays local-only. Review prompt for your agent: "List the tables added in this migration; for each, state whether it needs syncing and why; anything unnecessary gets marked local-only."
Anti-pattern #3: stuffing business logic into the sync channel
"Send a push when sync completes," "compute stats while syncing" — sync is infrastructure; its failure retries and out-of-order delivery will fire your business logic N times. Iron rule: the sync engine is only responsible for "data eventually consistent." Any side effect goes through a separate, idempotent task queue.
Anti-pattern #4: shipping without one real offline test
Toggling "offline" in the simulator doesn't count. The real test: a physical phone in airplane mode for three days. Ninety percent of local-first bugs (tombstone resurrection, queue reordering, token-expiry data wipes) only surface there. The checklist is the next section.
Anti-pattern #5: resolving conflicts by "asking the user"
A dialog saying "Conflict detected, please pick which version to keep" — users will curse and uninstall. Ninety-nine percent of conflicts should be auto-resolved by preset policy with a traceable record (a conflict log); only the rare money-and-permissions cases should ever interrupt the user. Remember: keep the complexity for yourself and give certainty to the user — that's the price you pay for the retention local-first buys.
The offline test checklist: 7 items before release
- Three days in airplane mode: a real phone, full features, three days, log every anomaly. The highest-ROI test there is. Nothing else comes close.
- Tombstone resurrection test: device A deletes a row offline, device B edits the same row offline, bring them online in sequence — deletion must win and B's edit must land in the conflict log, not resurrect the row.
- Queue replay test: make 20 mixed offline writes (creates, updates, deletes), restore connectivity, verify order is correct and nothing duplicated (idempotency-key dedup working).
- Flaky-network test: throttle to 2G with 30% packet loss for an hour — the app must not freeze and sync must eventually converge.
- Token-expiry test: let the token expire while offline — local data must be intact, syncing paused (not wiped), and resume after re-login.
- Cross-version test: data written by the old client must be readable and migratable by the new one; data written by the new client must not crash the old one (at minimum, unknown fields are ignored).
- Storage-quota test: fill local storage to the browser/OS quota (hundreds of MB to a few GB on mobile, varies) — the app must show a cleanup prompt, not fail writes silently.
The honest ledger: cost, payoff, and when not to bother
Some uncomfortable truth. The real cost of local-first for an indie developer: 2–4 weeks for the first conversion (one experienced hand + agent assistance), then ~30% extra on every schema change for compatibility work; conflict policy is designed once and tuned forever. The payoff: retention in weak-connectivity scenarios improves by an order of magnitude (an app that works offline in a commute is a cheat code), "doesn't work without internet" support tickets vanish, and there's an unexpected bonus — because the UI only reads locally, your pages render shockingly fast, and half the performance-optimization playbook becomes unnecessary.
When not to bother: ① pre-PMF — get 100 people willing to use it online first, then talk about offline; ② if even migrations feel like a chore, local-first will multiply that chore tenfold; ③ if the data is inherently centralized (market quotes, leaderboards, realtime auctions) — offline is meaningless there anyway, spend the energy on graceful degraded experiences instead.
One actionable close: tonight, have your agent grep the whole project for every UI file that calls a cloud API directly and list them. That list is your local-first conversion map — start at line one by moving reads to local. The architectural oath begins the day the network is evicted from your UI layer.
Comments (0)
Related articles
AI picks your stack for speed, not for year three. This guide gives solo developers a third path between toughing it out and rewriting from scratch: a six-step migration playbook where the old system stays live and every step rolls back.
Models are rented; data is owned. This guide gives solo developers the complete data-flywheel playbook: the four links and the minimum closed loop, collection design (the three questions), a lightweight labeling pipeline, dataset versioning and eval-set growth, four reflow paths ordered cheapest-first, cold-start data sources, and a one-page weekly checklist.
The CLI is the mother tongue of developer tools. When your users are developers, operations repeat at high frequency, and tasks fit into pipelines, the web page is a redundant middleman. This guide gives the full playbook for shipping a CLI from zero to one: the three-question decision test, --help-as-documentation UX, human/--json dual-mode output, Node/Python/Go/Rust selection, npm/pip/brew/cargo distribution, auto-updates, config and secrets, snapshot testing, and a v1 checklist.