Seven Ways Agents Die: From Infinite Loops to Confident Nonsense — A Failure-Mode Field Guide
Everyone who's coded with agents has seen it: stuck circling the same error, confidently delivering a completely wrong solution, quietly deleting your files. Agent failures aren't random — they follow fixed patterns. This guide catalogs the 7 most common deaths, each with symptoms, root cause, and a one-line countermeasure.
Why you need a field guide to deaths
When an agent breaks, beginners reach for 'try another model' or 'run it again.' Sometimes it works; more often it burns money. The truth: agent failure modes are highly repeatable — the same problems recur across projects and models. Naming the death wins you half the battle.
Death 1: infinite loop — circling the same error
Symptoms: the agent retries the same fix over and over, failing each time, saying 'let me try once more.' Your tokens drain; the error doesn't budge.
Root cause: it has no concept of giving up. Its loop is try → observe → adjust, but the adjustment space is locked by its own assumptions.
Countermeasure: set a hard cap (stop after 3 failures); force a rethink — 'redo it a completely different way, don't fix the current approach.' A human must referee from outside the loop.
Death 2: confident nonsense — wrong with conviction
Symptoms: the delivered solution looks complete, well-commented, self-consistent — but the core assumption is wrong. It never says 'I'm unsure,' only 'done.'
Root cause: models are trained to produce answers, not to admit ignorance. Uncertainty doesn't express itself automatically.
Countermeasure: demand the plan before the code; interrogate key decisions — 'are you sure? what are the counterexamples?'; core logic must have test coverage — tests are the one judge that doesn't listen to excuses.
Death 3: context loss — forgetting the beginning halfway through
Symptoms: mid-way through a long task, the agent re-asks settled questions or overturns its own earlier decisions.
Root cause: context windows are finite; early critical information got squeezed out. It didn't 'forget' — it can't see it anymore.
Countermeasure: slice tasks small, each independently verifiable; write key decisions into files (AGENTS.md or a decision log), not just the chat; have it periodically summarize state into documentation.
Death 4: permission overreach — hands faster than brain
Symptoms: it deleted without being asked; changed configs unprompted. April's PocketOS incident is the extreme case: an agent deleted a production database and its backups.
Root cause: default permissions too broad, and the agent doesn't grasp the weight of 'this action is irreversible.'
Countermeasure: start with least privilege; deletions, deploys, and outbound sends always need human confirmation; physically separate prod and dev.
Death 5: over-engineering — building you a cathedral
Symptoms: you asked for a simple script; it built a microservices architecture with a config center and plugin system.
Root cause: training data's 'good code' exemplars are mostly large projects; the agent can't tell demo from production.
Countermeasure: constrain in the prompt — 'minimal working implementation, no speculative extensibility'; make it present the plan first, you cut it down, then it writes.
Death 6: hallucinated dependencies — citing what doesn't exist
Symptoms: imports a nonexistent package, calls an undocumented API — all written convincingly.
Root cause: models generate probabilistically; an API name that 'sounds right' gets invented.
Countermeasure: running is the only truth — all code must actually execute; make the agent run tests itself instead of just showing you code.
Death 7: silent rot — slowly worsening, nobody notices
Symptoms: no errors, no failures, but code quality slides week over week: more duplication, sloppier naming, quietly dropping coverage.
Root cause: nobody reviews, so the agent's bar self-adjusts downward.
Countermeasure: regular (e.g., weekly) reviews by another agent or yourself; hard gates — lint must pass, coverage must not drop.
Our take: pin this guide to the wall
None of these seven deaths will be fully solved by better models — they're inherent to autonomous systems, not bugs. What separates veterans from beginners isn't model price; it's how fast you recognize which death you're looking at.
Save this guide. Next time the agent breaks, identify the death before acting. Right diagnosis, and the fix is often one line; wrong diagnosis, and every token is tuition.
Related articles
Prompts in vibe projects live in code strings, admin text boxes, and docs — changed live, version unknown when things break. This guide shows how to treat prompts like code: a prompts/ layout, YAML frontmatter, semantic versioning, PR reviews, canary rollouts with one-click rollback, plus an evals baseline — and a real war story: one added sentence cost 12 points of classification accuracy.
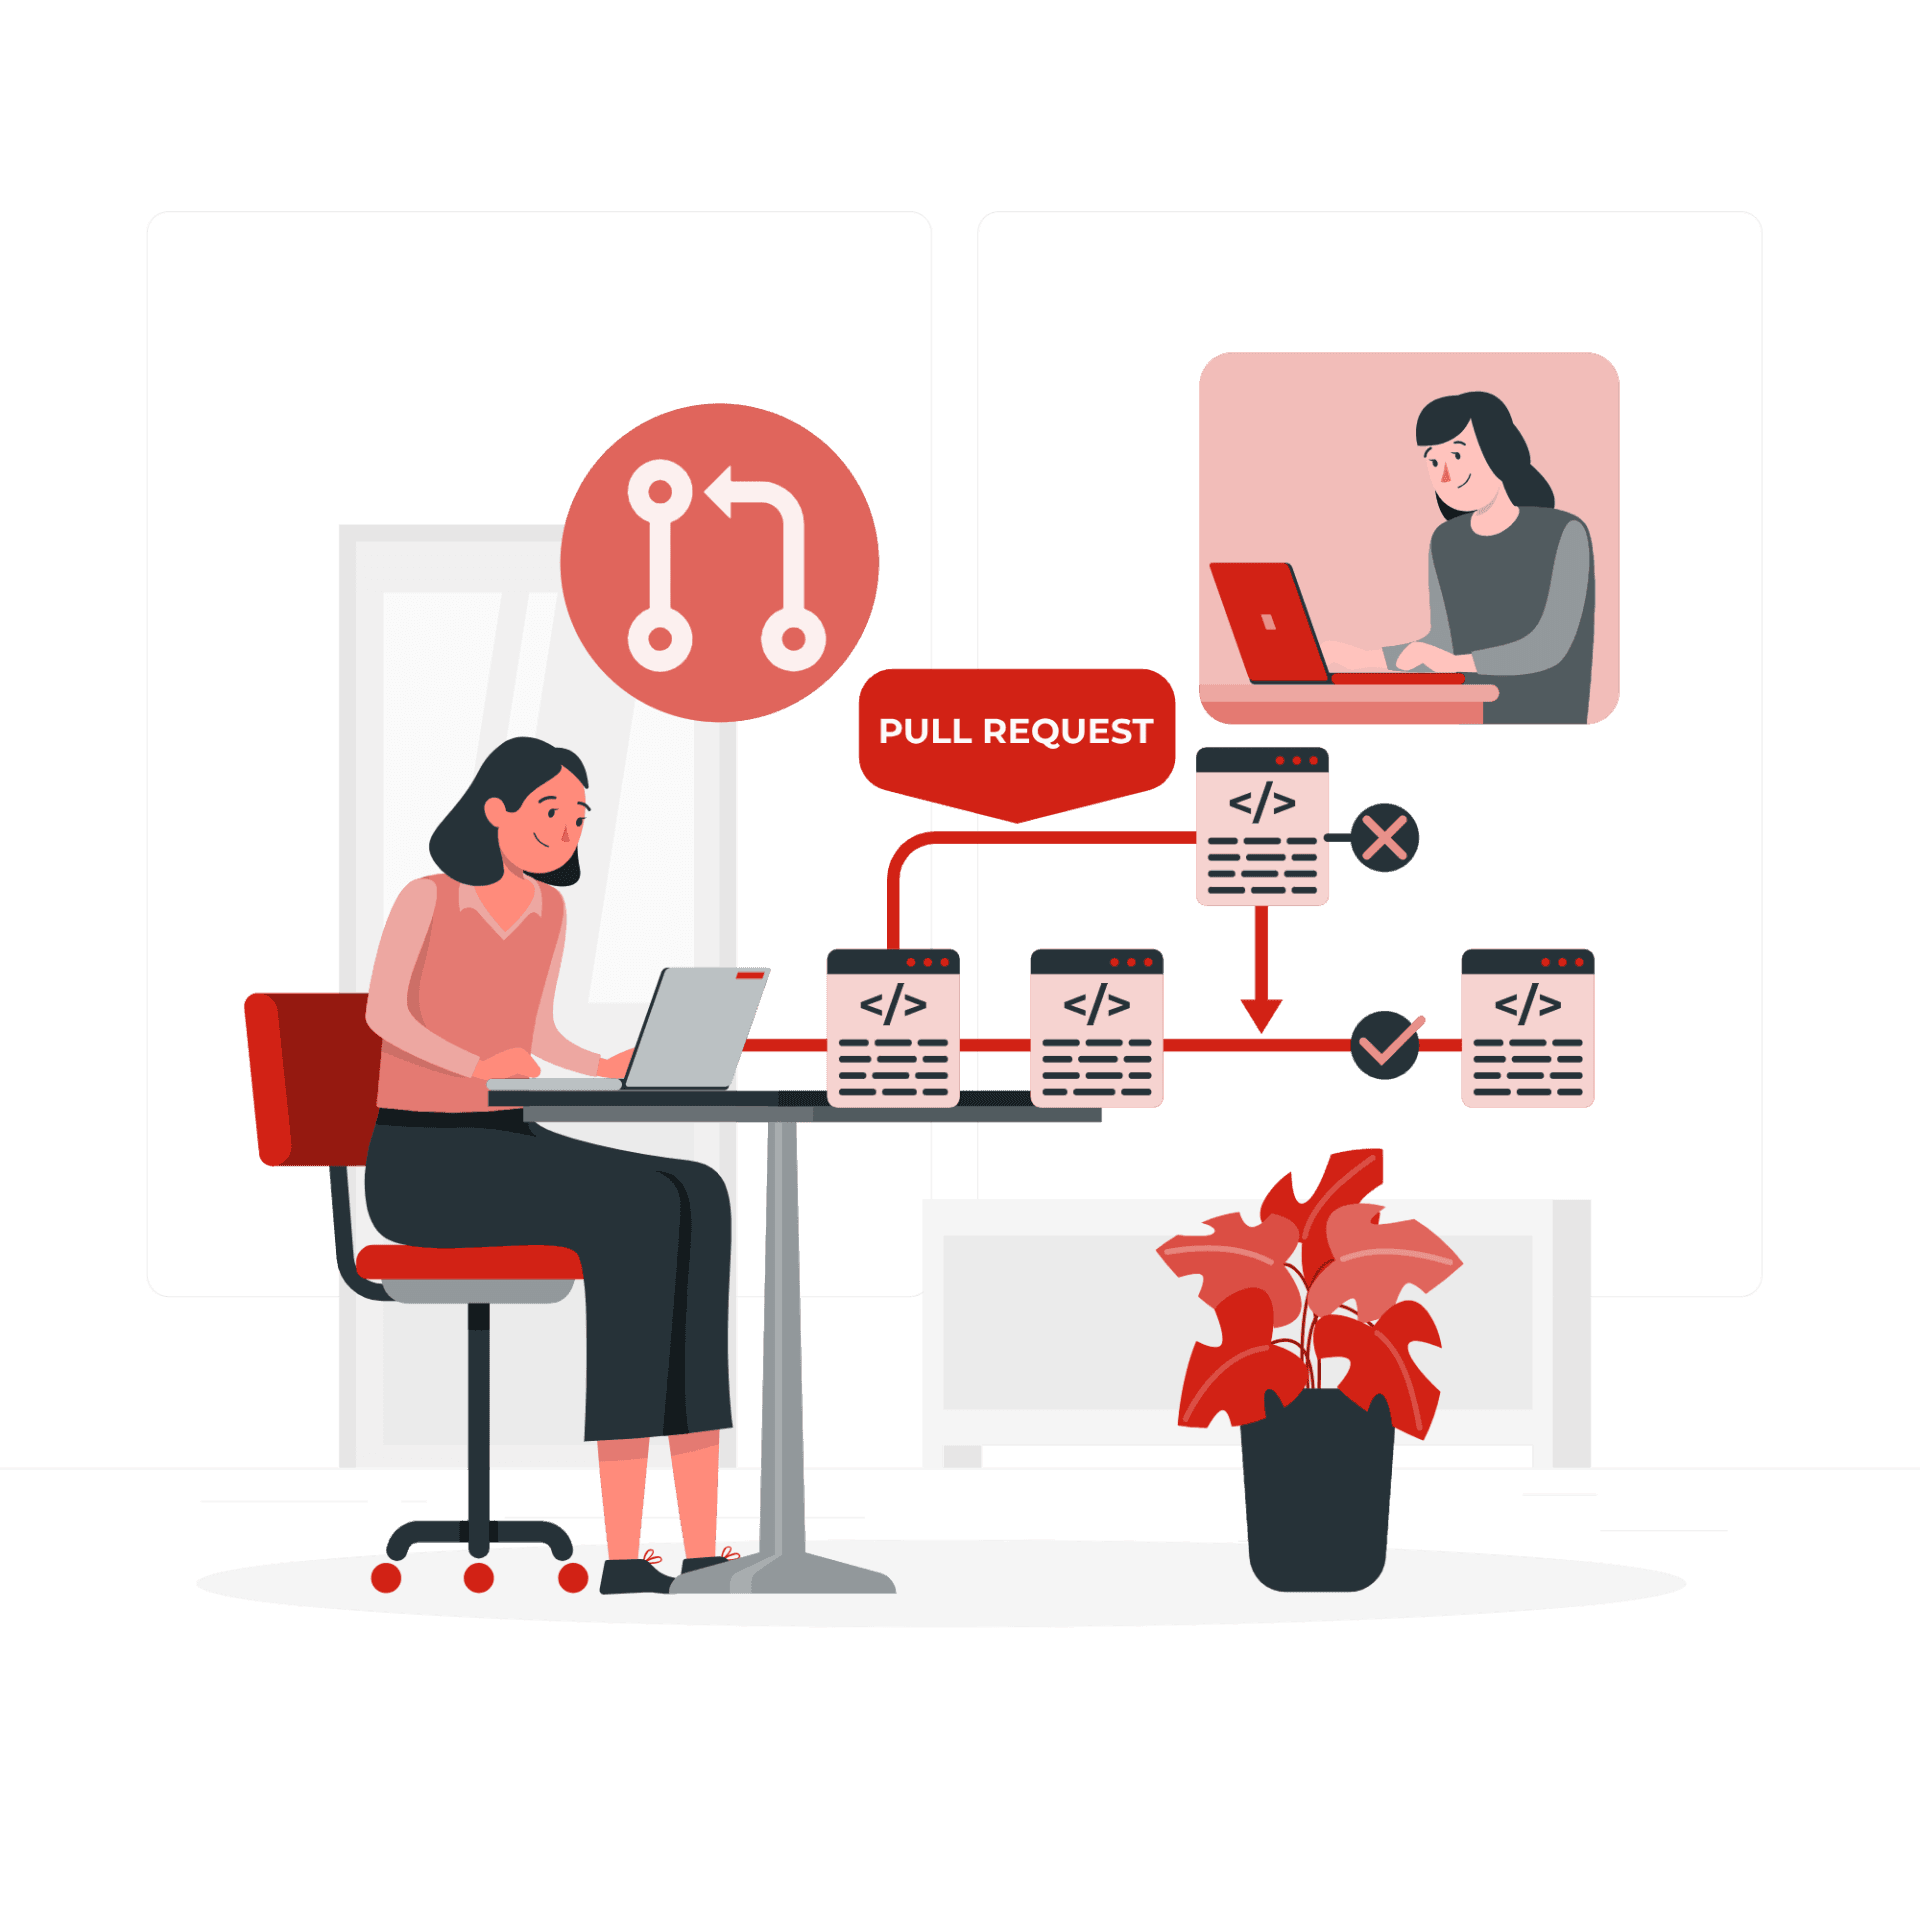
The faster AI writes code, the more review matters. Four layers: diffs for logic (boundaries, errors, concurrency — plus auth, payments, SQL, encryption, secrets), runtime for behavior (type checks, lint, security scans go green first), AI for first-pass screening (a second model reviews, humans read only flagged parts), humans for the final call (AI never clicks merge). Includes commit norms, PR template, branch protection, rollback plans.
Getting signups is only the start — users churn by day 3 and you have no horn to call them back. This guide covers notification systems for vibe projects: channel selection, email with Resend from day one, SPF/DKIM/DMARC done right, when SMS is worth the money, frequency caps and unsubscribe, retries and dead letters, plus a launch acceptance checklist.