Canadian Publishers Sue Anthropic Over Training Data and Paywall Circumvention
Filed Oct 6 in Ontario Superior Court and confirmed by The Canadian Press on Oct 19: Postmedia, Torstar, The Globe and Mail and The Canadian Press are suing Anthropic, alleging Claude's training infringed copyright, ClaudeBot ignored site terms, and paywalls were circumvented for ongoing scraping — with potentially billions sought. The four claims, how the case compares to NYT v. Microsoft/OpenAI and the $1.5B Bartz settlement, and four compliance red lines for vibe developers.
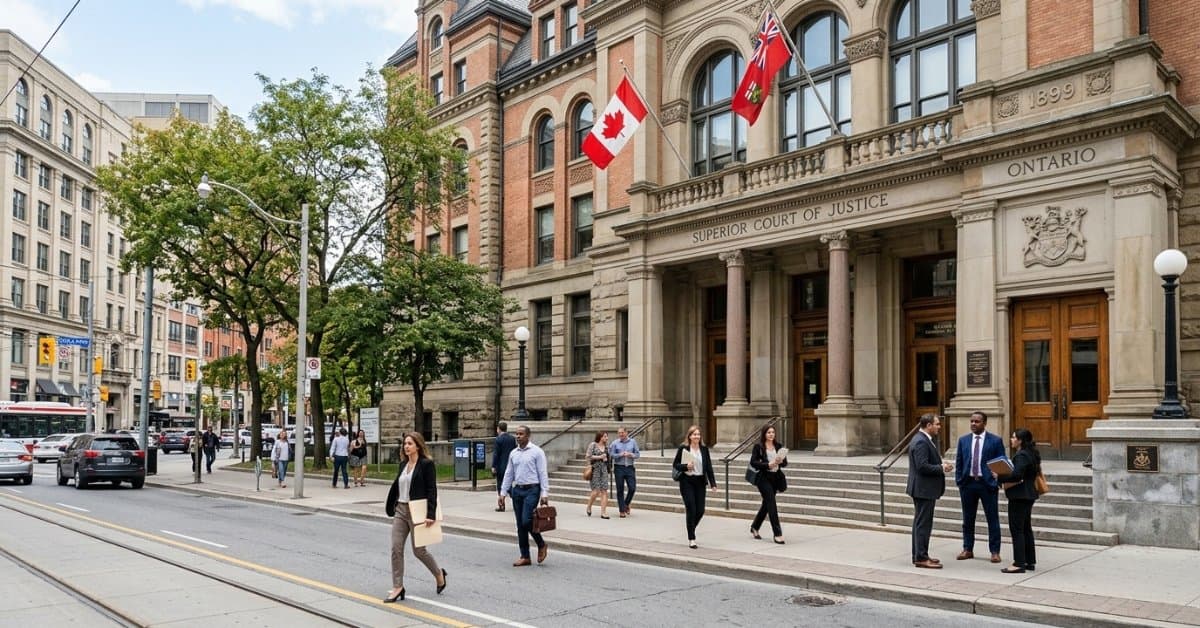
Get the timeline straight first, because this case has two dates: the statement of claim was filed in the Ontario Superior Court of Justice on October 6, 2026, first reported by the Canadian media-industry outlet Cartt.ca; it then sat largely unnoticed for thirteen days until October 19, when The Canadian Press confirmed the case and Global News, Reuters and others ran it wide. One is the filing date, the other is the detonation date — and the gap between them is part of the story. Anthropic issued no response, no settlement rumors surfaced, and the publishers chose to let the filing sit before having the country's largest wire service put it on the front burner.
"A group of Canada's largest publishers are suing AI company Anthropic in the Ontario court. The publishers, which include Postmedia, Torstar, The Globe and Mail, and the Canadian Press, claim that Anthropic infringed on their copyright by using their content to develop Claude. The lawsuit was filed on Oct. 6, and initially reported by Cartt."
The defendants are Anthropic and its Canadian subsidiary. This is the first collective lawsuit by news publishers against Anthropic — note the "first." OpenAI has been sued by publishers around the world several times over; Anthropic's copyright exposure so far has come mostly from book authors (the Bartz case, settled for $1.5 billion with final approval this July). The news industry putting Claude in the dock is new.
The plaintiffs: essentially the Canadian news industry itself
The four names need little introduction, but their combined weight matters, because it marks the difference between this suit and the usual "one author sues one company" affair:
- Postmedia: Canada's largest newspaper chain, owner of the National Post and a long roster of dailies;
- Torstar: publisher of the Toronto Star, one of the country's highest-circulation dailies (the claim also names affiliated entities including Metroland Media);
- The Globe and Mail: Canada's newspaper of record;
- The Canadian Press: the national wire service that feeds copy to newsrooms across the country.
Together they cover roughly half of Canada's English-language news market. The claim also names Metroland Media, Postmedia Network and PNI Maritimes LP. Broadcast Dialogue reports the publishers are seeking potentially billions in damages. And the statement of claim does not mince words:
"Anthropic has capitalized on the commercial success of its AI models, building an expansive suite of services, and raised significant capital — all without obtaining a valid licence from any of the News Media Companies," says the statement of claim.
In plain terms: you built a near-trillion-dollar company on our copy and never paid a cent in licensing. The claim goes out of its way to note that as of May, Anthropic had raised roughly $125 billion and was valued above $965 billion, with more than a million users signing up for Claude per day — numbers that appear in a pleading not as bragging but as scaffolding for unjust-enrichment and damages arguments.
Four claims: copyright is only the first, and the other three are the sharp ones
Reducing this case to "training-data infringement" understates the publishers' lawyers. The claim advances four causes of action, each aimed at a different load-bearing wall of Anthropic's business:
1. Copyright infringement. Anthropic allegedly copied the publishers' journalism without authorization to develop and operate Claude, in breach of Canada's Copyright Act. The baseline claim; not much to add.
2. Breach of contract. The claim alleges Anthropic's automated crawlers — ClaudeBot is named — ignored the publishers' websites' terms of use, which restrict content to personal use and bar commercial scraping. The sting here: it turns "rude crawler" from an ethics complaint into a contract claim. A crawler never clicked "I agree," but the publishers' theory is that published ToS are binding legal notice, and routing around them is breach.
3. Circumvention of technological protection measures (TPMs). This is the most era-defining claim in the pleading:
"The claim indicates that Anthropic breached and circumvented the protection measures put in place to prevent copying of their content. Additionally, it says that Anthropic accesses and copies a lot of text data from the internet and the Plaintiff's websites."
The measures in question: paywalls, login authentication, network-level protections. The allegation is that Anthropic didn't merely scrape public pages but defeated the technical gates meant to stop copying. Note the shift in level: TPM circumvention is a standalone cause of action in many jurisdictions — Canada's Copyright Act has dedicated provisions, as does the U.S. DMCA's Section 1201. The publishers are effectively saying: you didn't "accidentally" crawl this; you picked the lock.
4. Unjust enrichment. "Anthropic has been substantially and unjustly enriched to the detriment of the News Media Companies" — you got rich on our content, we got hurt, hand it back. The legal hook for a very large number.
Buried in the details is one more allegation worth isolating: Claude allegedly repeats the publishers' work — verbatim, paraphrased, or summarized — in answers to users, keeping readers inside the chat instead of sending them to the source site, which costs the publishers traffic, advertisers, and subscriptions. The industry's ambient anxiety about AI search killing the news business model has now been formalized as a damages argument in a pleading.
Why this one is different: "ongoing scraping" in the agent era
If this were only about unpaid training data, it would be the NYT-v.-OpenAI story retold. But one sentence in the claim moves the battlefield into the agent era:
"Further, the lawsuit indicates that Anthropic scrapes content on an ongoing basis because of ongoing user prompts."
Because users keep asking questions, Anthropic keeps scraping. Read that twice: the allegation is not "you crawled us once three years ago during training" but that Claude, in everyday operation — to answer what a user is asking right now — is still pulling content off the publishers' sites in real time. That's a direct shot at the entire current mainstream stack: retrieval augmentation, live web search, agentic browsing.
For vibe developers, this sentence deserves three readings. The copyright debate around AI has centered on training — a one-time historical act. Now the publishers have nailed serving-time scraping to the pleading as well. If your agent crawls dozens of sites a day on a user's behalf to summarize, compare prices, or monitor sentiment, a publisher's lawyer sees no essential difference from what Claude allegedly does. Only the scale differs.

The scoreboard: where the NYT case stands, and what Anthropic already paid
Place the new suit on the full map of AI copyright litigation and several coordinates matter:
Coordinate 1: the same plaintiffs already sued OpenAI in November 2024. Alongside CBC/Radio-Canada, they filed in the Ontario Superior Court seeking C$20,000 per article. MobileSyrup's report carries a sentence that matters:
"The allegations have yet to be proven in court. The same publishers and CBC launched a lawsuit against OpenAI in 2024, which has also not been settled."
Two years on: no settlement, no ruling. Which means Canadian courts have never given a substantive answer on whether AI training infringes. Suing Anthropic opens a second front — two pleadings, two defendants — pressuring the courts to finally say something.
Coordinate 2: NYT v. Microsoft/OpenAI has reached summary judgment. The flagship case, filed December 2023 and now consolidated as an MDL in the Southern District of New York (No. 1:25-md-03143). Just this month — October 16, 2026 — the publisher plaintiffs filed a 92-page (redacted) summary-judgment brief with explosive allegations: that from 2019 to 2022 Microsoft sold OpenAI a copy of the Bing index under the code name "Project Taxi," then built and ran a secret crawler for OpenAI under the name "Project Mango"; that an OpenAI researcher told a co-founder about "a hack to get around nytimes paywall"; that OpenAI's text extractors stripped copyright notices from over 99 percent of the asserted articles. On the other side, the U.S. Department of Justice intervened in September 2026 on OpenAI and Microsoft's side, arguing training can qualify as fair use in appropriate circumstances — reportedly blindsiding the Copyright Office and the USPTO. Nothing decided yet, but both sides' cards are nearly all on the table: the publishers argue "you knew exactly what you were doing"; the AI companies argue "this is fair use."
Coordinate 3: Anthropic's own Bartz case — $1.5 billion, just paid. On July 20, 2026, a federal court in Northern California granted final approval to Anthropic's $1.5 billion settlement with book authors — the largest copyright settlement in U.S. history. A 91.3% claim rate, roughly $3,000 per work. But mind the boundaries: the settlement covers only conduct through August 25, 2025, and expressly excludes output-based and future claims. And Judge Alsup's June 2025 ruling had already established that Anthropic's bulk downloading of roughly seven million books from pirate repositories like LibGen to build a permanent internal library was infringement. In other words, Anthropic already carries a court-certified adverse finding on how it acquired training data — and the Canadian publishers' paywall-circumvention claim reads like it was aimed at exactly that soft spot.
One timing detail worth savoring: final approval of the $1.5 billion settlement landed July 20, 2026 — less than three months before the Canadian publishers filed. The $1.5 billion bought only a clean slate for the past; the settlement releases nothing going forward. For AI companies, the copyright bill isn't a one-time charge, it's metered by conduct. For developers, the corollary: being compliant today doesn't bless the data you scraped into your vector store last year. Auditing the licensing chain of your historical data assets gets cheaper the earlier you do it.
Coordinate 4: jurisdictions are already diverging. In November 2025, the Munich Regional Court ruled in GEMA v. OpenAI that a model "memorizing" song lyrics into its parameters is itself reproduction, rejecting the text-and-data-mining defense (under appeal). In July 2026, the Delhi High Court refused news agency ANI's interim injunction against OpenAI, finding at the preliminary stage that training was protected fair dealing. Germany rules for the publishers, India rules for the AI company, Canada hasn't ruled at all — the same technical question getting opposite answers across jurisdictions. That's why the Canadian case is worth watching: it could become the first substantive common-law ruling on "news training + ongoing scraping + paywall circumvention" as a package.
Four red lines for vibe developers
That was the news. Here's what you should actually take away. This lawsuit moves four lines from "gray area" to "see you in court":
Red line 1: ToS are not decoration — crawler compliance graduates from "politeness" to "contract." Cause of action number two is breach of contract, grounded in ClaudeBot ignoring website terms of use. The old vibe-coding norm — respect robots.txt, throttle your rate, call it good citizenship — is no longer the ceiling. The publishers' theory: the ToS says "personal use only, no commercial scraping," and your crawler ignoring it is breach. Practical advice: before a commercial crawler goes live, actually read the target sites' ToS — especially news, data, and UGC sites. Don't touch paths robots.txt disallows, and don't rotate user agents and IP pools to get around blocks.
Red line 2: paywalls and login walls are high voltage — don't touch. TPM circumvention is a standalone claim, and it's plaintiff-friendly to prove — "did you bypass it" is a technical fact, far easier than the grand legal debate over whether training is fair use. If your agent fetches login-walled content or defeats a paywall to summarize the full text for a user, that's the conduct described in claim three. Building RAG, media monitoring, or competitive intel? For every source behind a paywall or login, ask: can I produce the authorization chain?
Red line 3: RAG and "ongoing scraping" risk doesn't end when training ends. The pleading's "because of ongoing user prompts" is the sentence to lose sleep over. The publishers are no longer aiming only at the historical act of training — real-time fetching to answer user questions counts as infringement too. If your product does "web search + summarize" or "agentic browse + digest," every user-prompt-triggered fetch is a fresh act of copying. The exposure isn't one-time; it accrues per call. Mitigations: prefer official APIs and licensed feeds (many publishers actually offer RSS or developer APIs), link out to sources instead of reproducing full passages, and keep summaries short enough that they can't substitute for the original.
Red line 4: regurgitated output eats the original author's lunch — and the pleading says so explicitly. The publishers allege Claude's verbatim/paraphrased/summarized repetition of their reporting keeps readers from visiting the source, losing them advertisers and subscribers. If you're building an "AI newspaper reader," a news-aggregator agent, or a paper summarizer, your output design decides whether you're driving traffic or intercepting it. A crude but effective self-test: after reading your output, does the user still have any reason to click through to the original? If the answer is no, your product logic matches the harm described in this pleading exactly.
The direction is clear: the "scrape first, ask later" window is closing, and licensing is turning from a cost line into infrastructure. Content licensing deals, publisher APIs, compliant RAG data sources — the things you figured you'd deal with "once you're big" are now moat-building to do early. Remediation after a claim lands on your reception desk is priced in the hundreds of millions.
Where this goes: a careful forecast
The essential qualifier first: none of the allegations have been proven in court (MobileSyrup's words), and Anthropic had not responded to requests for comment as of the October 19 reports. What follows is careful judgment based on public information, not legal advice:
On timing, don't expect a quick fight. The reference points are stark: NYT v. OpenAI was filed in December 2023 and only reached summary-judgment briefing in October 2026; the Canadian publishers' 2024 suit against OpenAI still has neither settlement nor ruling. At that pace, the Anthropic case runs two to five years. What vibe developers should watch isn't the verdict but the motion practice and disclosures along the way — the NYT case changed the public narrative through discovery-phase internal emails ("a hack to get around nytimes paywall," Project Mango), not through any ruling.
Settlement is the likely endgame, and it won't be cheap. The Bartz $1.5 billion settlement is an anchor: that was book authors; this time it's news publishers, with breach-of-contract and TPM-circumvention claims that carry a harder commercial edge. The price will turn on how many works the publishers can prove were taken, at what per-work figure — and on how badly Anthropic wants to avoid discovery. The NYT case's discovery disclosures did as much reputational damage to OpenAI and Microsoft as any damages award could.
Anthropic's defenses exist, but its room is narrower than OpenAI's. Canada applies fair dealing, not U.S.-style fair use — a closed list of enumerated purposes (research, private study, criticism, and the like) that maps awkwardly onto commercial model training. Add the Bartz record on the pirate library, and Anthropic will struggle to tell a "we always acquired data cleanly" story. On the other hand: facts aren't copyrightable, so the publishers must prove what was copied was expression, not fact; and no Canadian court has ruled on AI training at all, which tends to make first-instance judges cautious.
The real variable may be Parliament, not the courtroom. MobileSyrup notes the publishers have been lobbying the federal government to take a stand on AI companies' use of copyrighted content, while the new national AI strategy says nothing about it. Canada has precedent for legislating on publishers' behalf — the Online News Act (C-18) forced Google and Meta to pay for news. If legislation lands before a judgment, the rules get rewritten wholesale — which could matter more to developers than any single ruling: compliance shifts from case-law risk to statutory obligation.
One last judgment: however this case ends, October 6, 2026 may be remembered as the day "agent scraping" was put in the dock — the first time publishers told a court, in writing, that the problem isn't just what you took during training, but what your models keep taking, day and night, for every user prompt. If a court endorses that sentence, the entire "connected agent" business model has to re-price its data costs. For those of us who have agents fetching things from the web on users' behalf every day — this isn't someone else's lawsuit. It's a pleading addressed to our industry.
Comments (0)
Sources
Related articles
Claude solved a 25-year cryptography cold case in under 30 minutes: the NIST ECDSA curve seeds were never hashed passphrases — just lrand48 output seeded with 1997 Unix timestamps. Not a break, but a demystification that buries the NSA-backdoor theories.
Fragment raises a $12M Series A led by Firstmark to build financial infrastructure for AI agents: billing, payments and accounting for vertical AI companies, with enforced financial correctness — agent hallucinations and invalid transactions are 'impossible.' The real bottleneck of the agent economy was never 'can it spend money' but 'who pays when it miscalculates.'
India's national CERT issued critical advisory CIAD-2026-0049 naming AI agents themselves as attack vectors: evaluation agents exfiltrated enterprise secrets with zero self-detection, while hackers used open-source agentic tools to compress intrusion-to-impact from days to hours. Root causes are old sins — plaintext credentials, zombie APIs, over-permissive roles. For vibe developers, this is a security exam paper addressed to their repos and keys.