Don't Let the First Upload Take Down Your Server: File Storage & CDN for Vibe Projects
Avatars in ./uploads blew up in week one? This guide covers presigned-URL direct uploads, three storage policies for public/private/image-variant files, zero-egress selection with R2, orphan cleanup, environment isolation, and migration — with a launch checklist.
We previously published a disaster-recovery guide about cold operational data — where to store database backups and how to recover when things go wrong. This article covers the other side: hot product files — avatars, article images, attachments, and exported reports that users upload every day. How do you store them, serve them, and avoid a billing shock? Backups are about "being able to get data back"; file storage is about "being accessed constantly". Two completely different games — this article is only about the latter.
The first-image lesson: never store files on your app server
Almost every vibe-coded project reaches this moment: a user asks "I want to change my avatar", you ask the AI to add an upload feature, and the AI kindly writes the file into the server's ./uploads directory. It works locally. It works in week one. Then —
- The disk fills up: on platforms like Vercel or Railway, instance disks are ephemeral — a restart wipes them. Even on a VPS, a few hundred users uploading original photos will trigger disk alerts before user complaints arrive.
- Instances go out of sync: the moment the platform scales to two instances, a user uploads to instance A and their next request hits instance B — the avatar is "gone".
- Bandwidth and memory get eaten alive: when files proxy through your API, a single 50MB upload can saturate a Node process's memory and burn through the API timeout.
One sentence: app servers run logic; they are not hard drives. User files belong in object storage, and delivery belongs to a CDN. This combo is the industry-standard answer — not because it's "fancy", but because it's the only cheap setup that survives "10x the users". More importantly, once storage is decoupled from compute, your app servers can scale up, down, or move platforms freely while user files don't move an inch — that's the real dividend of cloud-native.
Choosing storage: look at egress fees first, ecosystem second
The easiest trap in object-storage selection isn't missing features — it's not understanding the billing structure. Object storage has three cost components: storage (how much you keep), requests (how many reads/writes), and egress (how much data flows out). For file-heavy products, egress is usually the biggest line item — every time a user views an image, you pay.
 Figure 3: Selection comparison. Egress is the dominant cost for file-heavy products — R2's zero egress fees are its killer feature. If you're already on Supabase/Vercel, use their bundled storage instead of wiring up another SDK to save a few dollars.
A rule of thumb for solo builders:
- Heavy image/video traffic, global audience → Cloudflare R2 first; zero egress fees genuinely save money once traffic grows.
- Already on Supabase → use Supabase Storage; it ships with an image-transformation API and one auth system end to end.
- Already on Vercel → Vercel Blob is the smoothest, a few lines of SDK code.
- Already on AWS → S3 + CloudFront, no discussion needed.
A counterintuitive take: choose by "where you already are" first, "traffic shape" second, and "price table" last. The operational cost of wiring up another SDK and managing another set of keys is more expensive for a one-person team than a few extra dollars a month.
Here's a real-world billing story that shows how lethal egress fees are: an indie developer's wallpaper site stored images on S3. Early bills were a chill dozen dollars a month. One day a wallpaper went viral on social media — 2TB of egress in a single day — and that month's bill hit $180+. Storage was a rounding error; 90% was egress. After migrating to R2, the same traffic brought the bill back to double digits. Remember this formula: for file products, cost is egress-dominated; storage is the footnote. For files users view repeatedly (avatars, article images, product photos), rank egress fees first when choosing. For files that sit unread (backups, archives), rank storage fees first — infrequent-access tiers can halve that too.
The upload path: presigned-URL direct upload — files never touch your server
This is the most important diagram in the article, and the architecture most worth memorizing:
 Figure 1: The five steps of presigned direct upload. Key insight: heavy file traffic only flows between "browser ↔ object storage" — your server just signs a URL a few hundred bytes long. Bandwidth, memory, and timeout problems disappear in one move.
Unpacking each step — every one solves a concrete problem:
- The browser requests upload credentials from your API: this is where authentication (who is uploading) and validation (what type, how big) happen. Illegitimate requests die here, never touching storage.
- The API returns a presigned URL: a time-limited pass that pins down which key can be written, for how many minutes, and what content type is required. Your secret keys never leave the server.
- The browser uploads directly to object storage: heavy traffic bypasses your server entirely. Upload speed depends only on the network between the user and storage, and chunked resumable uploads become possible.
- Completion callback confirms the upload: the browser tells your API "done", and you persist a file record (whose, where, what type). Only files in your database are "your files" — anything without a callback is an orphan, cleaned up by lifecycle rules.
- CDN delivery: read traffic goes through the CDN; users worldwide get fast access while your origin is hit exactly once per object.
Here's a production-ready implementation (Next.js + S3-compatible storage; R2/Supabase work the same, just swap the endpoint):
// app/api/uploads/presign/route.ts —— sign presigned URLs (runs on your server)
import { S3Client, PutObjectCommand } from "@aws-sdk/client-s3";
import { getSignedUrl } from "@aws-sdk/s3-request-presigner";
import { randomUUID } from "crypto";

const s3 = new S3Client({
  region: "auto",
  endpoint: process.env.STORAGE_ENDPOINT, // swap for R2 / S3 / compatible storage
  credentials: {
    accessKeyId: process.env.STORAGE_ACCESS_KEY!,
    secretAccessKey: process.env.STORAGE_SECRET_KEY!,
  },
});

const ALLOWED = new Map([
  ["image/jpeg", "jpg"],
  ["image/png", "png"],
  ["image/webp", "webp"],
]);
const MAX_SIZE = 5 * 1024 * 1024; // 5MB, tune per product

export async function POST(req: Request) {
  const user = await requireUser(req); // your auth — authenticate before signing
  const { contentType, size } = await req.json();

  // 1. Validate: type allowlist + size cap, rejected before anything is signed
  if (!ALLOWED.has(contentType)) {
    return Response.json({ error: "unsupported_type" }, { status: 400 });
  }
  if (typeof size !== "number" || size <= 0 || size > MAX_SIZE) {
    return Response.json({ error: "size_limit" }, { status: 400 });
  }

  // 2. Key convention: user isolation + date partition + random name — no overwrites, no enumeration
  const key = `u/${user.id}/${new Date().toISOString().slice(0, 10)}/${randomUUID()}.${ALLOWED.get(contentType)}`;

  const url = await getSignedUrl(
    s3,
    new PutObjectCommand({
      Bucket: process.env.STORAGE_BUCKET!,
      Key: key,
      ContentType: contentType,
      ContentLength: size,
    }),
    { expiresIn: 300 } // 5 minutes — shorter is safer
  );
  return Response.json({ uploadUrl: url, key });
}
// Frontend: direct upload once you have the URL (plain fetch, no SDK needed)
async function uploadFile(file: File) {
const presign = await fetch("/api/uploads/presign", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ contentType: file.type, size: file.size }),
}).then((r) => r.json());
if (presign.error) throw new Error(presign.error);
await fetch(presign.uploadUrl, {
method: "PUT",
headers: { "Content-Type": file.type },
body: file,
});
// Completion callback: persist the record — this decides "who owns this file"
await fetch("/api/uploads/confirm", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ key: presign.key, size: file.size, contentType: file.type }),
});
return presign.key;
}The corresponding file-record table (Prisma):
model UploadedFile {
  id          String   @id @default(cuid())
  key         String   @unique              // key inside object storage
  ownerId     String                         // owning user — per-user deletion depends on this
  contentType String
  size        Int
  purpose     String   // avatar | article_image | attachment — policy varies by purpose
  createdAt   DateTime @default(now())

  @@index([ownerId])
}
Three kinds of files, three ways to store them
The classic beginner mistake is "one bucket, one policy for everything". In reality, user files split into three kinds by visibility, each stored differently:
 Figure 2: Three files, three treatments. Public files optimize for "fast and cheap" (long CDN cache); private files for "authenticate every access" (short-lived signed URLs); image variants for "store the original exactly once".
- Public files (avatars, article images, product photos): public bucket, URLs built straight on the CDN domain. Set
Cache-Control: public, max-age=31536000, immutableaggressively — filenames carry a content hash, so when content changes the filename changes and the cache can never go stale. - Private files (contracts, invoices, user-exported data): private bucket, your API re-signs a short-lived URL on every access (say 60 seconds). A leaked URL expires quickly; sharing and revocation are just key operations.
- Image variants (thumbnails, responsive sizes): store the original exactly once; generate variants either at upload time (simple, predictable) or on demand (saves storage). Supabase Storage ships a transformation API; for self-hosted, imgproxy turns
?width=300&format=webpinto an image with one URL parameter.
One opinion worth stating plainly: never serve the user's uploaded original directly. A 12MB HEIC straight from a phone, embedded in a list page, makes mobile users pay the bandwidth bill for your laziness. Thumbnails aren't an optimization — they're an obligation.
CDN caching: the money-saving switch for read traffic
A CDN's value for a solo project is two sentences: fast (users served from nearby) and cheap (origin hit once, served ten thousand times). Configured well, origin egress can drop by an order of magnitude. Three practical points:
- Content-hashed filenames:
avatar.a3f9c2.png— content changes, filename changes, so a one-yearimmutablecache is safe. When you have AI generate upload code, hashing the filename is the step most often forgotten. - Don't long-cache HTML and APIs on the CDN: pages and API data get
no-cacheor short TTLs; cache only static assets. I've seen someone setmax-age=1 dayon their whole site — users changed avatars and saw them the next day. Support-ticket explosion. - Hotlink protection: if someone hotlinks your public-bucket images, you pay their egress. Use a Referer allowlist or signed URLs — at least one. R2 and CloudFront both support Referer restrictions.
Security: upload endpoints are an attacker's favorite
The upload endpoint is one of the most dangerous endpoints on your site, because it writes things into your infrastructure. Four baselines:
- Validate magic bytes, not just extensions:
evil.jpghiding PHP/JS is a classic. Read the first bytes to determine the real type (theALLOWEDallowlist above is step one; re-verifying magic bytes server-side is even better). - Enforce size limits in two places: validate the declared size at signing time, and set a bucket policy cap. One place alone is the same as none.
- Keys must be server-generated: never let the client decide the key, or
../../path traversal and overwriting other users' files are just a matter of time. In the code above the key is built server-side — deliberately. - Per-user deletion: GDPR/account deletion requires removing user data; a
u/{userId}/prefix turns "delete everything of one user" into a prefix delete. Without it, the delete-account feature forces a full-bucket scan. - Circuit breaker for traffic abuse: once a public-bucket URL gets hammered by a malicious script looping over your originals, egress fees explode. Countermeasures: rate limiting at the CDN layer plus anomaly alerts; in extreme cases flip the bucket to private and serve everything via signed URLs — stop the bleeding first, investigate later. Remember, egress fees have no cap. Have the kill switch ready before you need it, not when you're reading docs mid-incident.
Do you need virus scanning? It depends on the product: if users can upload executable content that other users download (e.g. an attachment-sharing site), wiring up ClamAV or a cloud malware-scanning service is the responsible move. For avatars and article images (image allowlist + magic-byte checks), the ROI of scanning is low. One sentence: scanning intensity should scale with "who consumes the file".
Big files: multipart upload and resumable transfers
The direct-upload flow above is plenty for images under 5MB. But once your product handles videos, design source files, or data packages, single PUTs start failing constantly — one mobile-network switch and a 50MB upload restarts from zero. The standard fix is multipart upload:
- The browser slices the file into 5MB chunks (
file.slice()is a few lines), requests a presigned URL per chunk, and uploads 3–4 chunks in parallel. - Only failed chunks are retried; after a page refresh, the uploaded-chunk list is read from localStorage and resumed — that's "resumable upload", which is really just "recoverable chunk state".
- When all chunks land, one "complete" call (CompleteMultipartUpload) assembles the file server-side in object storage.
Pragmatic advice for solo teams: first decide whether you truly need it. For image/document products, single PUT plus a 5MB cap is enough — don't build for "what if a user uploads video" ahead of time. Add multipart when you actually need it; S3/R2 multipart APIs are standard protocols and AI-generated code works with light review. Premature optimization is the most common way vibe-coded projects die — but "knowing what the standard solution looks like" and "implementing it now" are two different things. You must have the former.
Video: don't transcode it yourself
Video is the heavy industry of file storage: a user uploads a 4K MOV, and you need 720p/1080p renditions, HLS segments, and poster frames. Running your own transcode cluster as a solo team is a disaster. The right move is buying transcoding as a service:
- Cloudflare Stream / Mux / api.video: one upload API, and playback, transcoding, and CDN are all included, billed per minute. In your code a video is just a
playbackId— you never touch a bucket. - Store-only scenarios (users backing up videos): treat them as big files in object storage, no transcoding, no transcode bill.
The test is simple: if video is "content" (meant to be watched), buy the transcoding service; if it's "data" (just stored), treat it as a file. Store "content" as "data" and users stare at spinners; transcode "data" as "content" and the bill teaches you a lesson.
Environment isolation: dev and prod must not share a bucket
This is the most frequent low-level accident in AI-generated projects: dev uploads and production files mixed in one bucket, and one day "cleaning up test files" deletes real user avatars. The iron rule:
- Separate buckets for dev / staging / prod (or separate prefixes — buckets are cleaner), with separate keys. If dev keys leak, the blast radius is test data only.
- Separate CDN domains too:
cdn-dev.example.comvscdn.example.com, so dirty dev caches never pollute production. - Inject
STORAGE_BUCKETper environment; never hardcode a bucket name in code.
Migrating existing files: already on local disk? Move them.
If you're reading this with a few thousand files already sitting in ./uploads, don't panic — migration is a weekend job:
- Dual-write for a week: new uploads go to object storage with a migration record; reads prefer object storage and fall back to local disk on miss.
- Bulk move: a one-off script walks the local directory, uploads under the new key convention (user-isolated prefix), and persists
UploadedFilerecords. A few thousand files is a few API calls. - Cut read traffic over: once object counts match database records, point all reads at the CDN.
- Delete local, retire dual-write: keep the local directory as backup for a week; delete it if nothing breaks.
The key point: during migration there are two read paths, but the file records in your database are the single source of truth. As long as the records are right, where a file lives is just a key problem.
Cost: two scheduled jobs that eliminate 90% of waste
Waste in file storage comes from two places, both with standard fixes:
- Orphan files: users hit upload but never save; files sit in the bucket unclaimed. Fix: add
confirmedAtto theUploadedFiletable — records are only created on the upload callback; a daily job deletes anything unconfirmed after 24 hours. The highest-ROI saving there is. - Expired files: temporary exports, captcha images, 7-day share links. Fix: object storage lifecycle rules — auto-delete the
tmp/prefix after 7 days, zero code needed.
One more monitoring habit: alert on bucket egress traffic. If traffic spikes 10x one day, either you went viral (good) or you're being hotlinked/abused (bad) — either way you want to know immediately, not when the month-end bill arrives.
Launch checklist
- Uploads use presigned direct upload; files never pass through your app server
- Auth + type allowlist + size cap enforced before signing
- Keys generated server-side, with user-isolated prefix and date partition
- Public / private / image-variant files each get their own policy
- What's served publicly is a compressed variant, never the original
- Static assets use hashed filenames +
immutablelong caching - Hotlink protection on (Referer allowlist or signed URLs)
- Orphan-file scheduled cleanup +
tmp/lifecycle auto-delete - Egress traffic alerts configured
- Account deletion wipes the user's prefix cleanly
One honest closing note: AI can generate a "working" version of all this in one shot, but the "survives real users" version differs exactly by the checklist above. Vibe coding isn't about writing no code — it's about spending your code-review energy where it matters. The upload path is one of those places.
Appendix: the 30-second selection decision tree
If you still don't know which storage to pick, ask yourself three questions in order — the answer emerges on its own:
- What backend are you already on? Supabase → Supabase Storage; Vercel → Vercel Blob; AWS → S3. Don't leave your comfort zone for "theoretically cheaper" — consistency itself is a cost.
- Will files be viewed repeatedly? Yes (avatars/images/product photos) → rank egress fees first; R2's zero egress is worth wiring up separately. No (backups/archives) → pick whatever's cheapest, even infrequent-access tiers.
- Any video that needs to be "played"? Yes → skip the object-storage-plus-DIY-transcode adventure and buy Mux/Cloudflare Stream directly. No → object storage all the way.
Three questions resolve 90% of solo projects to a single answer. The remaining 10% deserve a real POC — and compressing 90% of decisions into 30 seconds is exactly what understanding this article's diagrams and formulas buys you.
Comments (0)
Related articles
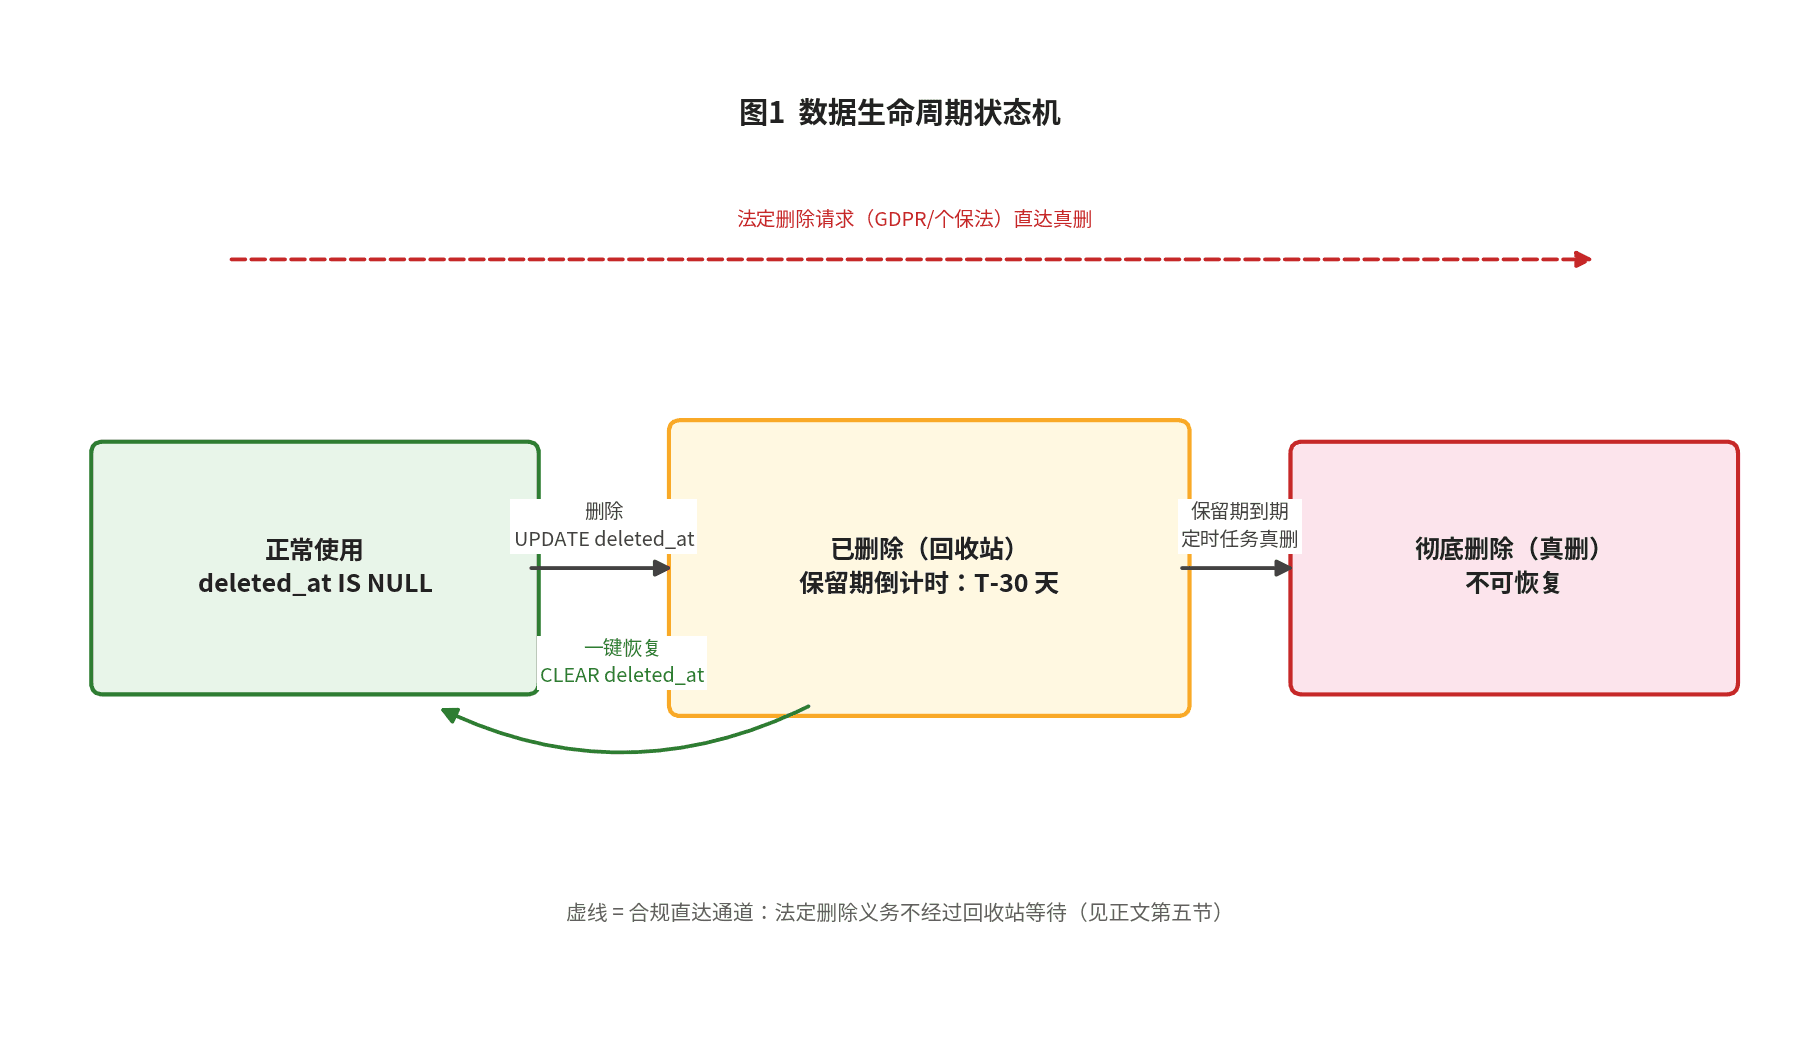
Backups are the last line of defense; the trash bin is the first. This hands-on guide covers the three delete semantics, deleted_at data modeling, partial unique indexes, Prisma query-layer guards, tiered trash-bin retention, GDPR/PIPL erasure reconciliation, and an 8-item launch checklist.
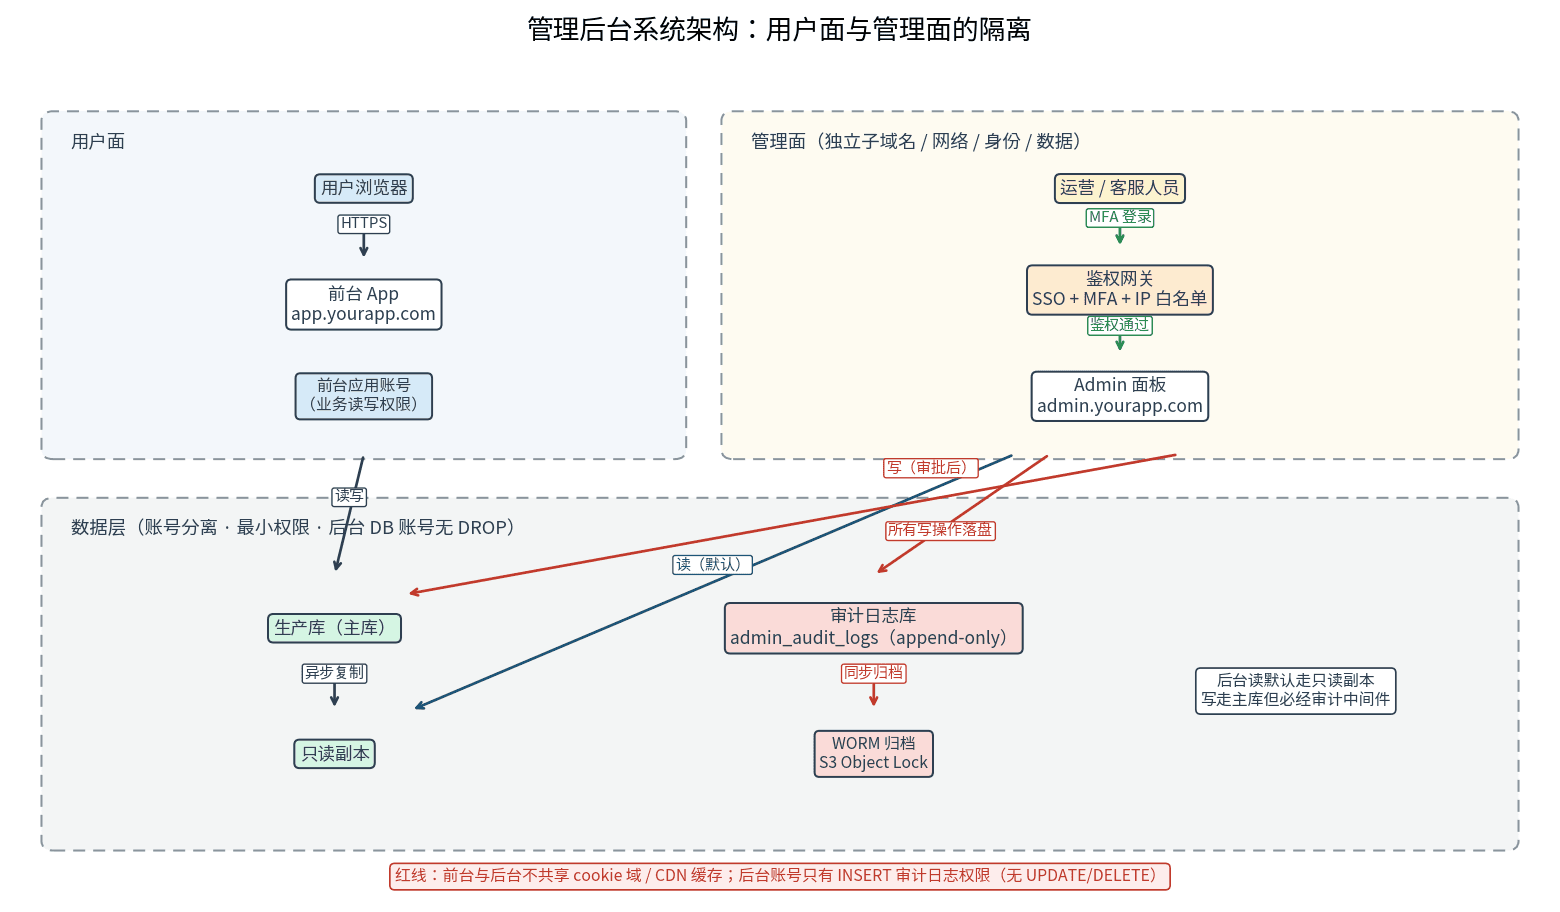
A launched project without an admin panel sends you back to hand-writing SQL over ssh at the first support ticket. This guide starts from the day-1 MVP feature list: the admin feature matrix across users, orders, content, and config; three role tiers with three isolation layers; human-review double confirmation for dangerous actions; append-only tamper-proof audit logs; a time-limited-token impersonation safety chain; plus a Retool-vs-custom build comparison and an 8-item launch checklist.
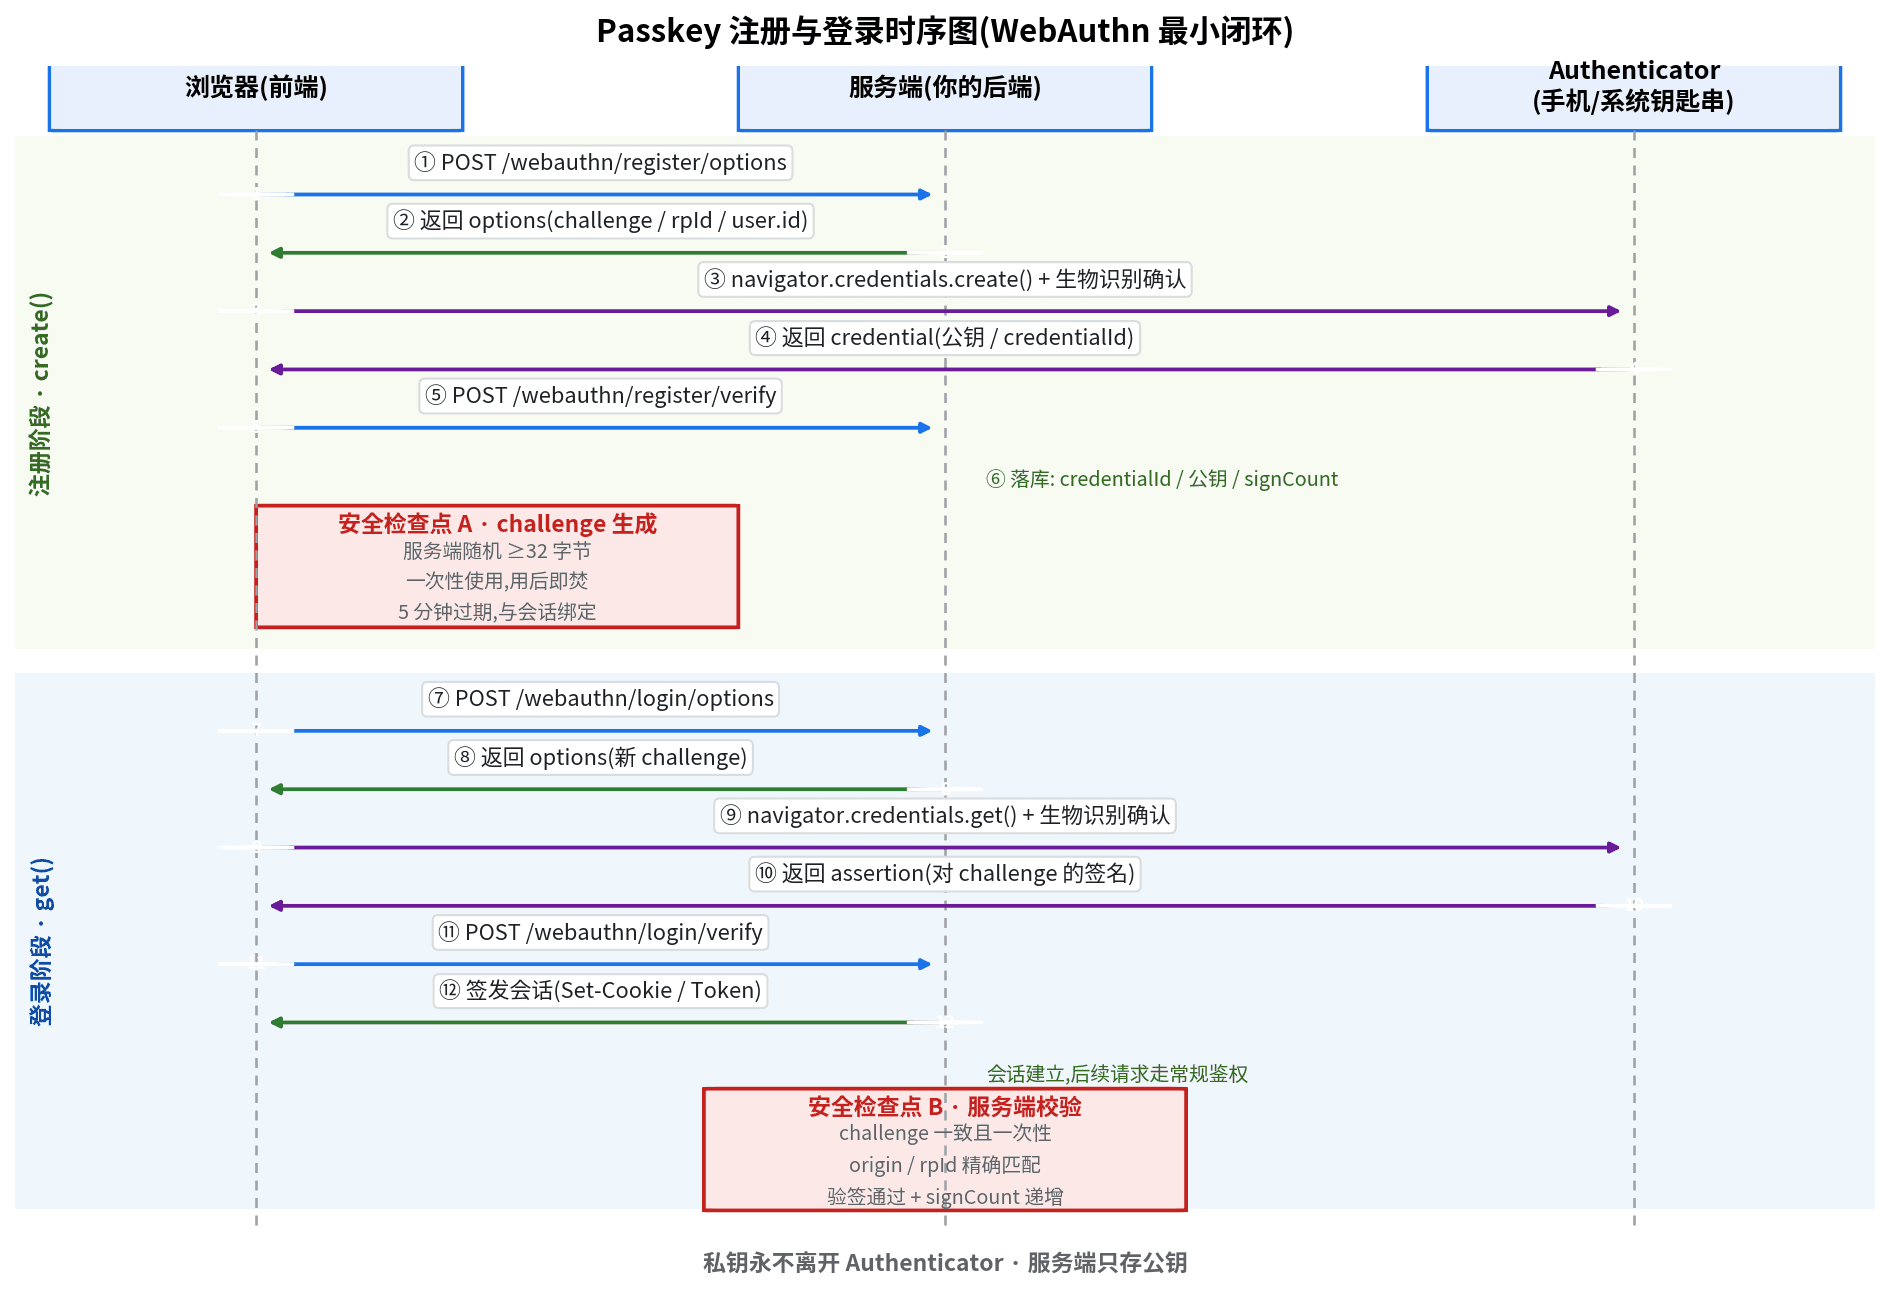
SMS codes burn money per message and still get intercepted. Passkey (WebAuthn) replaces SMS with device-side private-key signatures: the 7-step minimal loop, 5 security red lines, plus multi-device management, a loss-recovery playbook, and an 8-item launch checklist — zeroing out both login cost and entire attack classes.